By Greg Nowak. Updated 10 November 2026.
You want potential customers to find your website. You may also want to refuse AI training crawlers, reduce unwanted traffic, or keep client documents private. Those goals need different controls, and a blanket “block AI” setting can work against your marketing.
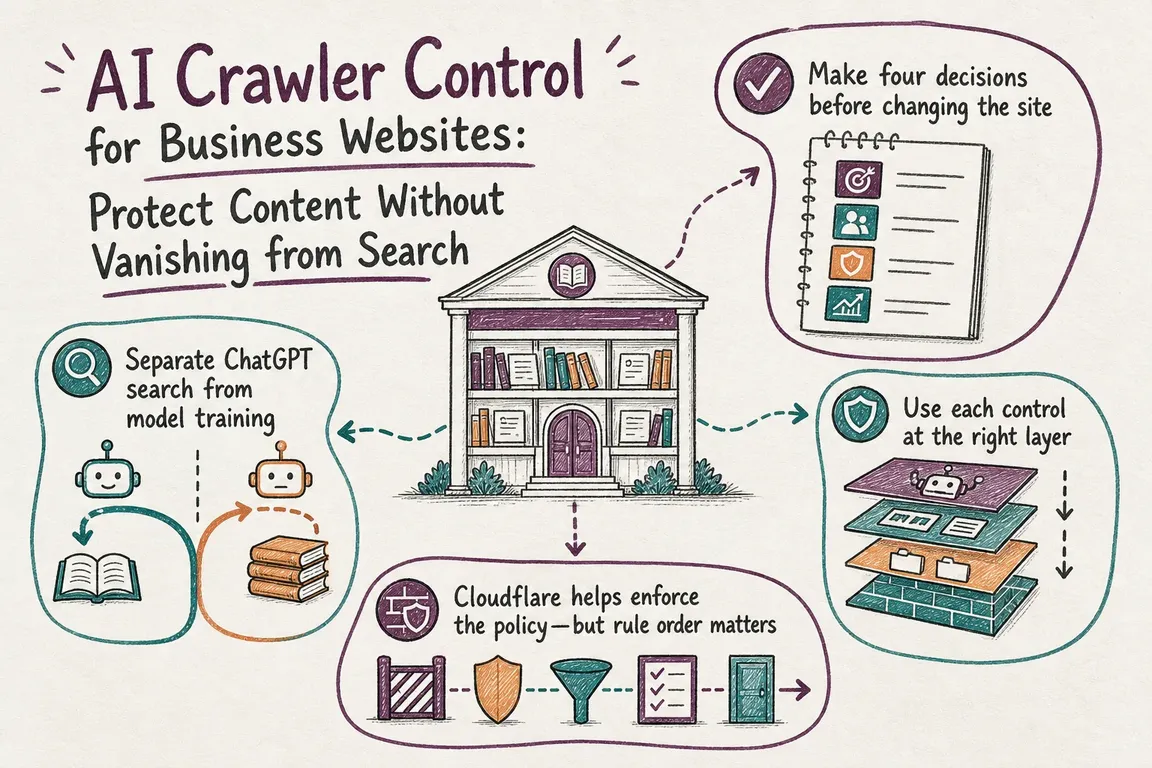
A useful crawler policy starts with the business decision: what should remain discoverable, what use do you want to refuse, and what should require permission to open? Then make your CMS, hosting, and firewall agree.
Decide what each type of content is for
Start with a service page, an article, a public download, an internal search page, and a client area. Ask the content owner what should happen to each. A sales brochure and a client proposal may both be PDFs; that does not make them equally public.
| Your goal | Control to consider | What it cannot guarantee |
|---|---|---|
| Keep service pages discoverable | Allow relevant search crawlers and indexing | Inclusion, rankings, or enquiries |
| Allow ChatGPT search, refuse training | Allow OAI-SearchBot; disallow GPTBot | A universal opt-out across AI providers |
| Limit Google search previews | Selected-text or page-level snippet controls | Protection against copying |
| Keep a public PDF out of search | X-Robots-Tag: noindex | Confidentiality or restricted downloads |
| Protect proposals and client files | Authentication and appropriate permissions | Protection for files left outside those controls |
robots.txt is a request to cooperating crawlers. It does not enforce privacy. The Robots Exclusion Protocol standard explicitly distinguishes it from access security. Require authentication for confidential material, including direct download URLs.
Allow ChatGPT search while refusing GPTBot
OpenAI’s crawler documentation separates OAI-SearchBot for ChatGPT search from GPTBot, which gathers content that may be used for model training. You can allow the former and disallow the latter independently.
For that policy, this is a starting example:
User-agent: OAI-SearchBot
Allow: /
Disallow: /internal-search/
Disallow: /preview/

User-agent: GPTBot
Disallow: /

User-agent: *
Disallow: /internal-search/
Disallow: /preview/
Replace the sample paths and merge these rules into your existing file. Preserve necessary CMS restrictions and sitemap declarations. Do not paste them over a working policy without reviewing existing named groups.
The repeated paths matter. A matching named group does not inherit the fallback User-agent: * rules under RFC 9309’s group-selection rules. A dedicated group containing only Allow: / can therefore remove restrictions you expected to retain.
OpenAI also recommends permitting its published search crawler IP ranges. Its search systems can take approximately 24 hours to adjust to robots.txt changes. ChatGPT-User handles certain user-triggered visits; robots.txt rules may not apply to those requests. Review other providers separately.
Understand Google’s visibility tradeoff
Google requires a page to be indexed and eligible for a search snippet before it can appear as a supporting link in AI Overviews or AI Mode. No special AI file or schema is required. Google’s AI features guidance also distinguishes Googlebot’s Search controls from Google-Extended, which concerns training and grounding in some other Google systems.
Choose snippet restrictions deliberately:
data-nosnippetexcludes selected text from snippets when applied to supported elements:span,div, orsection.max-snippetlimits snippet length and how much content may become direct input for Google’s AI search features, subject to separately permitted uses.nosnippetprevents text snippets and direct use of the content in AI Overviews and AI Mode.
For a public PDF that should stay out of search, return this HTTP response header:
X-Robots-Tag: noindexGoogle must crawl the URL to read this directive. Disallowing it in robots.txt can prevent that. The file remains publicly accessible. Google’s robots directive specifications explain these controls.
Check Cloudflare’s rules when settings and results disagree
Cloudflare AI Crawl Control implements crawler blocks through WAF custom rules. “Allow” does not override other security rules: an earlier rule may still block a wanted crawler. Earlier skip rules can also bypass an intended block.
Inspect the matching security events and rule order before changing another setting. Cloudflare warns that direct edits to the underlying WAF rule are not reflected back in the AI Crawl Control dashboard. Its WAF integration guidance explains the interactions.
Verify production before calling the job finished
Save the existing configuration and record how to restore it. Replace example.com below with your domain:
curl -sS -L https://example.com/robots.txt
curl -sS -L -D - -o /dev/null https://example.com/services/
curl -sS -L -D - -o /dev/null https://example.com/brochure.pdf
-L follows redirects. Inspect the final response status and headers; the commands show preceding responses too. They do not display HTML robots tags. Check those in page source or Google Search Console’s URL Inspection.
- Confirm private pages and direct files deny unauthenticated access.
- Check relevant hostnames, including staging and download domains.
- Review actual crawler requests in server logs and firewall events. A successful curl request does not prove crawler access.
- Monitor indexing, referrals, and enquiries after deployment. Retest after CMS, hosting, or firewall changes.
Give the policy an owner
The handover should record the agreed policy, representative URLs, configuration locations, rollback steps, and who maintains each layer. For agencies, make the boundary between client, delivery team, and hosting provider explicit.
If those responsibilities are spread across several people, Greg can help audit the setup and coordinate implementation. See how Greg works as your digital project manager.
Related on GrN.dk
- ChatGPT Visibility Without Opening Every Door: robots.txt Is Only the Start
- AI crawler policy now has verbs: separate search, RAG, and training
- Google’s AI Search Toggle Is a Publishing Decision, Not an SEO Setting
Need help with this kind of work?
Discuss your website’s crawler policy with Greg Get in touch with Greg.










