By Greg Nowak. Last updated 2026-10-08.
If your agency uses OpenAI’s hosted Evals platform to check AI workflows, its closure creates a practical problem for the next prompt or model change. You still need to know what was tested, what counted as a pass, and which failures should stop a release.
Those decisions need to survive the migration alongside the test inputs. Whoever maintains the workflow afterwards should be able to run the checks and explain why it is ready to deploy.
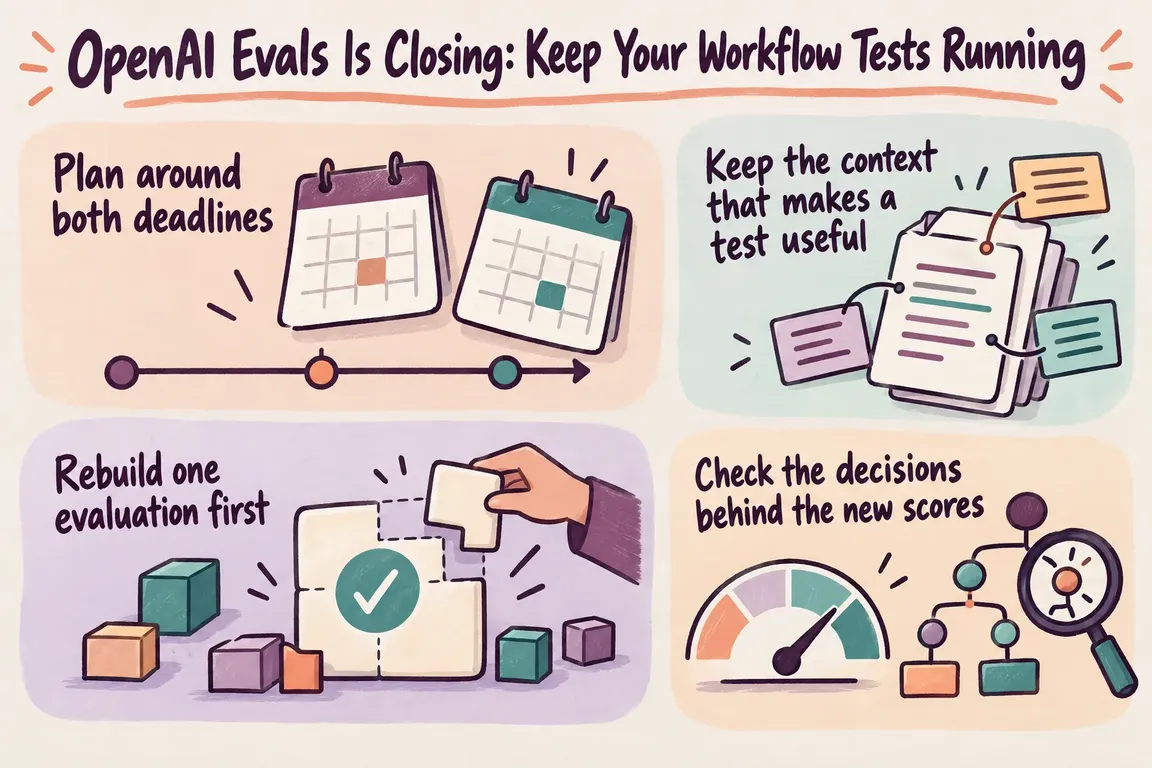
Plan around both deadlines
OpenAI’s deprecation schedule says existing evaluations become read-only on October 31, 2026. The Evals dashboard and API are scheduled to shut down on November 30, 2026. The graders documented for evaluation workflows are also part of the transition.
Aim to have a working replacement by October 31. That leaves the remaining transition window to investigate differences and finish the handover while you can still consult the hosted dashboard. Waiting until November 30 takes that reference away during the work.
Identify the releases that currently depend on hosted evaluations. Each needs an agreed testing route while you validate the replacement; otherwise, a platform migration can leave a delivery team without the checks it normally relies on.
Keep the context that makes a test useful
Start with an inventory by business workflow. Record who owns each evaluation, which behaviour it protects, and where its results affect a release decision. Give tests used in current delivery priority. Older experiments can have a separate archive status.
For each evaluation, preserve enough information for the next maintainer to understand both the test and the decision it supports.
| Asset | Keep | Ready when |
|---|---|---|
| Test cases | Inputs, expected outcomes, reference answers and relevant context. | Each case has a clear link to the behaviour it tests. |
| Prompts and configuration | Instructions, variables, model identifiers and relevant settings. | The replacement runs the intended version. |
| Grading criteria | Rules, rubrics, judge instructions and scoring definitions. | Reviewed examples show that grading is acceptable. |
| Historical results | Available outputs, scores, run dates and configuration references. | A maintainer can inspect the baseline used for earlier decisions. |
| Acceptance thresholds | Pass conditions, critical failures and review requirements. | The release owner can explain what blocks deployment. |
Keep historical results in an archive with the context needed to interpret them. If something is missing, label the gap. That lets the next maintainer judge what the archive can reliably tell them.
Thresholds deserve particular attention. A score alone may not explain whether a rule applies to the whole suite, one workflow or an essential behaviour. Write that down, along with who can approve an exception. These are release decisions that need to carry through to the replacement.
Rebuild one evaluation first
The OpenAI Cookbook migration guide describes manually recreating evaluations in Promptfoo. Prompts, providers, test cases and grading behaviour move into a portable configuration, with assertions and metrics replacing hosted testing criteria. The evaluations can then run locally or in continuous integration.
The guide does not rely on an OpenAI Evals export feature. New Promptfoo runs are separate from completed hosted runs, and workflows involving tools or agents may need additional configuration. Allow for that work when setting the scope.
Choose a pilot evaluation that protects a current workflow and has clear success criteria. Use it to settle the file structure, naming, review process and report format. Record any judgement calls made during the rebuild. The pilot then gives the rest of the migration a practical pattern, with unresolved questions visible before you repeat it across the suite.
Check the decisions behind the new scores
The Cookbook warns that similarity scores can differ between systems. Recreated graders, especially model judges, also need validation. An old numerical threshold producing a pass in the new runner does not, by itself, show that the replacement is grading correctly.
Compare individual pilot cases. Keep the inputs and intended behaviour fixed, then investigate where the graders disagree. Ask the workflow owner to review disputed outputs against the written criteria. For each disagreement, record whether it calls for a configuration correction, a clearer rubric or an intentional change to the acceptance rule.
Anthropic’s guidance on agent evaluations recommends repeated trials because outputs vary, and calibration of model judges against human expertise. It also recommends reading transcripts to separate genuine workflow failures from problems with the evaluation itself.
Include a comparison report in the handover. It should explain which release decisions remain consistent, where disagreement remains, and who accepted any revised criteria. That gives the release owner a basis for approving the replacement beyond comparing two overall scores.
For automations, check what actually happened
Anthropic distinguishes the agent’s transcript from the final state it leaves in the environment. That distinction matters when an automation is supposed to take an action: the evaluation needs to check whether the action happened.
For a workflow that updates a record, define a check against the resulting record in the test environment. Response quality can have its own check where it matters, but successful completion needs a separate criterion. Review these outcome checks during migration so the rebuilt suite still tests the business requirement.
Make the checks part of a release
Once you have validated the replacement, automate its execution before releases. Promptfoo’s CI/CD documentation describes evaluation runs, JSON and HTML reports, JUnit XML output, and quality gates that fail a build when thresholds are unmet. These give you ways to connect test results to deployment decisions.
Agree which changes trigger testing, where reviewers find the report, and who investigates failures. Require explicit acceptance of the run before deployment. If a particular behaviour is essential, give it a blocking check of its own; an overall pass rate can leave that requirement unclear.
Before handover, verify the gate with an intentionally failing test case. Keep evidence of both a successful run and a blocked release. Someone other than the implementer should be able to find the report and explain why the failure stopped deployment.
A manageable project with a clear finish
A scoped project with Greg through GrN.dk could begin with one agency workflow. The work would cover its evaluation inventory, preservation of available assets, a rebuild in a portable runner, a comparison of grading decisions, and release checks connected to the validated suite.
Agree the deliverables upfront: an asset inventory, runnable configuration, comparison report, documented acceptance thresholds and a demonstrated release check. Include a rerun and handover session so the agency can operate the suite after the project ends.
The inventory should determine the scope, including any custom workflow setup. Name a business owner for the success criteria and a technical owner for ongoing maintenance. That gives the project a clear finish and the team a dependable starting point for future prompt or model changes.
Contact Greg through GrN.dk to discuss a scoped evaluation migration before the October 31 read-only deadline.
Related on GrN.dk
- NGINX Can Read JSON Before Routing—Should It Handle Your AI API?
- OpenAI Has Machine Identity Now. Which Jobs Should Lose API Keys?
- Before You Buy a GPU: Test Your Team’s Local AI Workload
Need help with this kind of work?
Discuss your evaluation migration with Greg Get in touch with Greg.