By Greg Nowak. Last updated 2026-10-12.
Your service page looks complete in a browser. The offer is clear, the buying questions are answered and the product links work. Yet the HTML your server sends may contain much less. How much of the page only appears after JavaScript runs?
That gap matters when a system retrieving your content cannot execute JavaScript. Whether it exists on your site needs testing. Start by comparing the server response with the page a visitor sees, focusing on information customers need to understand what you sell.
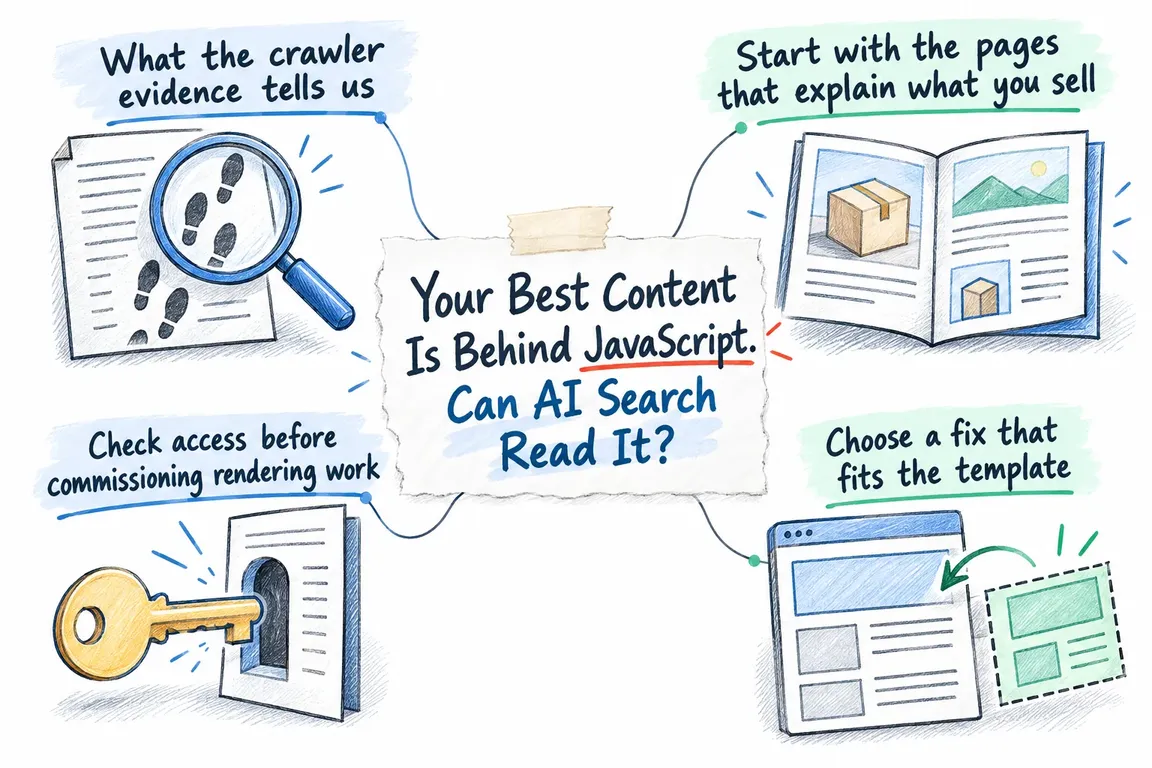
What the crawler evidence tells us
Vercel’s December 2024 crawler study found that several major AI crawlers it tested, including OpenAI, Anthropic and Perplexity agents, did not execute JavaScript. Some fetched JavaScript files, but that did not mean they rendered the page. Those findings describe the agents and conditions tested then. They give you a reason to investigate, while today’s access paths still need checking.
Google documents a different process. Its JavaScript SEO guidance explains how Googlebot processes the initial response, queues eligible pages for rendering and then processes the rendered HTML. Google still recommends server rendering or prerendering because some bots do not run JavaScript.
A successful Google rendering check therefore tells you about Google’s access. You cannot extend that result to every AI retrieval system. The presence of JavaScript alone tells you little, either. What matters is whether the page needs it to deliver the service description, product details or other essential content.
Start with the pages that explain what you sell
Choose representative service, product and category pages. Pay particular attention to CMS templates used across many URLs: a finding there gives the developer a defined set of pages to investigate. Include a page with substantial content and another with optional fields or an unusual combination of components.
For each page, agree what a prospective customer needs to know: what the offer is, who it serves, relevant specifications or limitations, and where to go next. Use the business’s approved copy as the reference. That keeps the work focused on whether the site delivers the content you already intend to publish.
Capture the HTTP response and the browser’s rendered page for the same URL. Compare the main heading, descriptive copy, product attributes, navigation links, title, meta description and canonical URL. Mark each item as present, missing or different, and label the response evidence separately from the rendered evidence. A developer should be able to reproduce the comparison.
A finding such as a service description appearing in the rendered page but missing from the response HTML is specific enough to act on. It identifies the content and the delivery gap. It does not establish that AI cannot read the whole website.
Check how the information is delivered, too. Vercel’s study notes that some non-HTML content, including JSON, may still be interpreted. Record embedded data separately from readable page content. For essential copy, meaningful HTML gives the implementation team a clearer acceptance target; a data payload alone does not establish that every target system can use it.
Check access before commissioning rendering work
First, decide which kinds of access the business wants to allow. Anthropic’s documentation dated 7 April 2026 distinguishes three agents. ClaudeBot collects content that may contribute to training, Claude-SearchBot supports search, and Claude-User retrieves content at a user’s direction. Anthropic says its bots honour robots.txt directives and do not bypass CAPTCHAs.
You can assess training access separately from search and user retrieval. Check the rules for each relevant agent against the business’s intended policy. A permission for one agent does not describe every Anthropic access path, and this documentation does not establish their current JavaScript rendering capabilities.
Review available server or CDN logs alongside the page comparisons. Record requested URLs, reported user agents, response statuses and timestamps. A user-agent label is a starting point for investigation. A log entry shows that a request occurred; it does not show that the requester rendered the page or understood the content.
Keep four things distinct in the report: permission to request a page, an observed request, the content delivered and any observed rendering. For retrieval tests, record the date and conditions. If the evidence leaves a gap, leave that question open rather than inferring what an AI answer must have accessed.
Choose a fix that fits the template
Vercel’s prerendering guide describes two ways to generate HTML on the server. Static site generation produces HTML at build time for reuse; server-side rendering produces it for each request. JavaScript can then make the delivered page interactive through hydration. The guide recommends frameworks with built-in prerendering.
The right choice depends on what is missing and how the content gets published. An audit finding does not, by itself, justify replacing the CMS or rebuilding the site. Use this table to narrow the options with the delivery team.
| What the audit finds | Option to assess | What must pass before sign-off |
|---|---|---|
| One component leaves essential copy out of otherwise complete response HTML | Fix the component or CMS template | The approved copy appears in the response on representative pages using the affected component or template |
| Public content can be published through a build process | Static generation or framework prerendering | A CMS publication reaches the generated HTML through a documented update process |
| Public content needs to be generated for each request | Server-side rendering | The response contains the current public content before JavaScript runs in the browser |
| Essential information is already present; interaction depends on JavaScript | Keep the interaction and verify content coverage | The response explains the offer, and the browser interactions still work |
Before choosing static generation, agree how a CMS edit becomes published HTML. For server rendering, specify which public information each response must contain. Give the editor and developer the same example pages and expected content. Naming a rendering approach is not enough to sign off the work.
Give the delivery team something they can use
Greg can help turn a focused audit into an implementation brief: representative URLs, comparisons between response HTML and rendered pages, access findings, affected templates and prioritised fixes. Each recommendation should name the missing information, a proposed owner and the evidence needed to accept the change.
Prioritise gaps that leave the offer unclear or remove links to important pages. Group related findings by template so the team can assess a correction across the URLs it affects. Keep unresolved questions in the brief, especially where current crawler behaviour has not been observed directly.
After deployment, repeat the comparisons and test a newly published or edited CMS page. Confirm that essential content reaches the response and that the browser experience still works. Those checks establish a concrete result the business can review. AI inclusion, citations and enquiries need separate monitoring; the audit does not establish or guarantee those outcomes.
Related on GrN.dk
- Your Site Search Knows Product Names. Can It Understand Customers?
- AI Content on Google: Which Pages Are Worth Keeping?
- From Supplier PDFs to Product Data: Where AI Needs a Second Check
Need help with this kind of work?
Discuss a crawl-accessibility audit Get in touch with Greg.