By Greg Nowak. Updated 21 September 2026.
An AI workflow can be technically successful and still be a poor business system. A customer waits too long for a reply, a research task dies when a connection closes, or thousands of routine classifications consume the same capacity as live requests. These are often routing problems, not model problems.
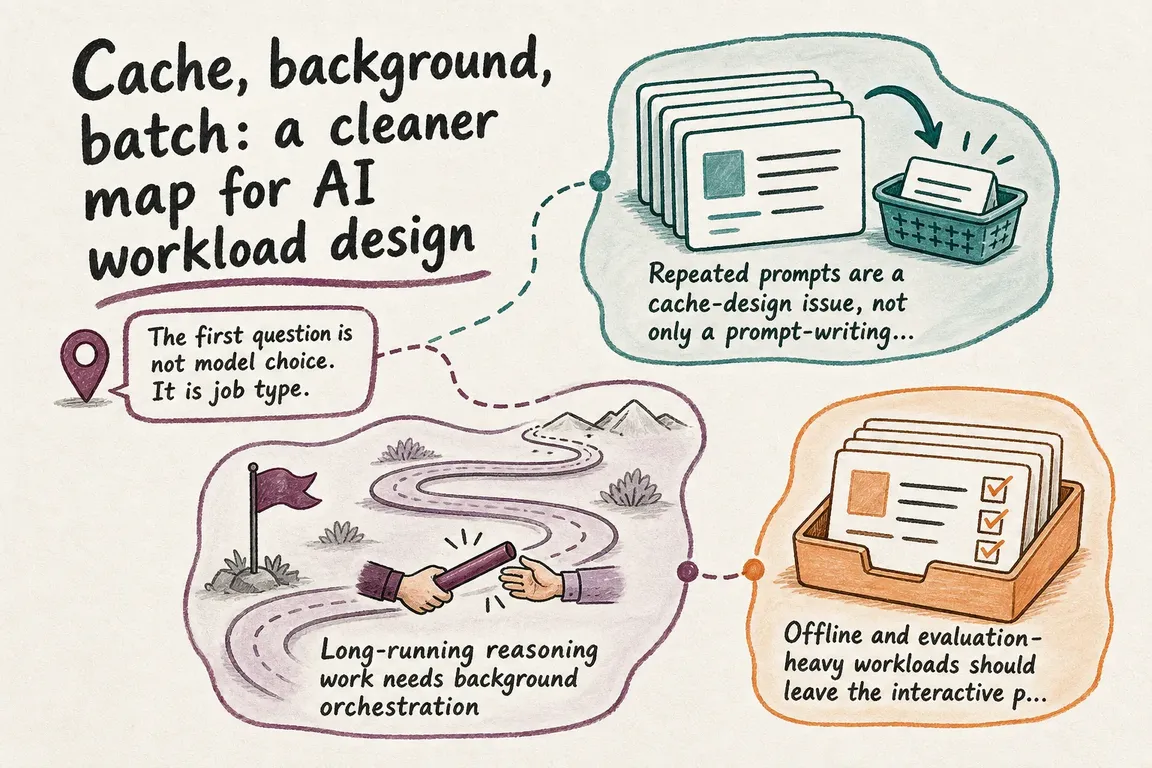
The practical fix is to give each job an operating lane. Use synchronous requests when somebody is waiting, background mode when completion may take minutes, and Batch when the work can finish later. Prompt caching is not a fourth lane; it is an optimization for repeated context within suitable requests.
Start with the service promise
Before choosing an API feature, ask what the business has promised. Does the answer need to appear during the current interaction? Can the user leave after receiving confirmation? Would completing the work by tomorrow be just as valuable?
| Business requirement | Recommended route | Good examples | Operational responsibility |
|---|---|---|---|
| A person is waiting | Synchronous, cache-aware request | Drafting assistance, live extraction, support copilot | Latency budget, timeout, fallback and concise context |
| The result may take minutes | Background response | Detailed research, complex analysis, long agent task | Job state, polling or webhook delivery, cancellation and expiry |
| The deadline is measured in hours | Batch API | Evaluations, bulk classification, embeddings and reprocessing | Input validation, ID reconciliation, partial failures and deletion |
A single product may use every route. A support platform could answer simple questions synchronously, accept a complex investigation as a background job, and evaluate the previous day’s conversations through Batch. That separation makes expectations, costs and failures easier to manage.
Use caching for genuinely reusable context
Prompt caching works on an unchanged prefix. Put stable instructions, tool definitions, schemas and reusable examples first. Put customer data, timestamps, request IDs and the immediate question afterwards. A small change near the beginning can prevent later content from being reused.
Do not pad a short prompt merely to qualify. For GPT-5.6 and later, the reusable prefix must contain at least 1,024 visible input tokens. These models support implicit caching and developer-selected boundaries using prompt_cache_breakpoint. When a changing suffix is unlikely to be reused, prompt_cache_options.mode: "explicit" lets you stop the cache write after the stable material.
The economics need measurement. On GPT-5.6 and later, a cache write costs 1.25 times the ordinary input-token rate, while a cache read costs 0.1 times that rate. Track cached_tokens, cache_write_tokens, latency and actual cost. Repeated writes with few subsequent reads are an expense, not a saving.
A stable prompt_cache_key can separate cache accounting by customer, user or workspace. It is optional and should not become a place for a new random value on every request.
Choose background mode when the connection should not own the job
Background mode is designed for Responses API tasks that may run for several minutes. Create the response with background=true, keep its response ID, and retrieve its status until it completes or fails.
The parameter is the easy part. The surrounding workflow needs a durable internal job record containing the response ID, customer, purpose, submission time, status and delivery channel. Add polling backoff or webhook handling, cancellation, an expiry policy, idempotent delivery and a failure message a non-technical user can understand.
Data handling also needs a precise review. Background requests from Zero Data Retention projects run with store=false, but response data is temporarily written to disk for roughly ten minutes to support asynchronous execution and polling. That temporary state should be documented in the data-flow review rather than described as either ordinary storage or no storage at all.
Use Batch when immediacy has no business value
OpenAI currently documents Batch as 50% less expensive than synchronous APIs, with a separate pool of substantially higher rate limits and completion within 24 hours. It is a strong fit for evaluation suites, bulk enrichment, classification, repository embeddings and backlog reprocessing.
Batch is an operating process, not just a cheaper loop. Requests are supplied in a JSONL file, and every line needs a unique custom_id. Output order is not guaranteed to match input order, so reconciliation must use that ID. An input file is limited to one model, which is another reason to validate routing before submission.
Start with a representative sample. Validate the schema and output quality, then submit the larger file. Keep counts for accepted, completed, failed and expired records; retry only the appropriate failures. Store the input file ID, batch ID and output file ID alongside your own job record so an operator can investigate discrepancies.
Cleanup must have an owner. OpenAI’s data-control documentation lists application state for /v1/batches as retained until deleted. Treat deletion of completed batch objects and associated files as a scheduled operational task, not an informal promise.
Make governance part of routing
“OpenAI retention” is not one setting. Abuse-monitoring logs, stored responses, temporary background state, prompt-cache tensors, uploaded files and batch objects have different lifecycles. Eligibility for controls such as Zero Data Retention also depends on the organization and feature.
For each lane, record the data class, purpose, remote identifiers, access rules, retention period, deletion method and accountable owner. Then test the promise specific to that lane: latency and fallback for synchronous work, state transitions and duplicate delivery for background work, and completeness and reconciliation for Batch.
A practical rollout sequence
- Inventory current AI calls and label each one interactive, long-running or delay-tolerant.
- Record its deadline, volume, data sensitivity, failure consequence and business owner.
- Stabilize reusable prompt prefixes and establish a baseline for latency, cache usage and cost.
- Pilot one background workflow with durable job state and one small Batch file with reliable ID reconciliation.
- Document retention and deletion responsibilities with the security or compliance owner.
- Add lane-specific alerts and quality checks before increasing volume.
The goal is not to adopt every OpenAI feature. It is to give each workload the least expensive, most dependable route that still meets its service, quality and governance requirements.
Need a practical workload map?
If every AI task still travels through the same synchronous endpoint, Greg can help classify the work, expose the operational trade-offs and turn the redesign into an implementable delivery plan. Talk to Greg about your AI workflow.
Related on GrN.dk
- Not Every AI Job Needs an Instant Answer: Batch the Backlog
- A Voice Agent Is Only Ready When the Human Handoff Works
- AI automations need a spend dashboard before the first runaway bill
Need help with this kind of work?
Talk to Greg about your AI workflow Get in touch with Greg.