By Greg Nowak. Updated 23 September 2026.
Teaching a support bot is the easy part. The more revealing question is what happens when an article becomes wrong.
A refund policy changes. A product is retired. An unsafe workaround is unpublished. The page may vanish from the help center immediately, yet copies can remain in exports, extracted text, chunks, embeddings, search indexes, caches, evaluation datasets, or another language version.
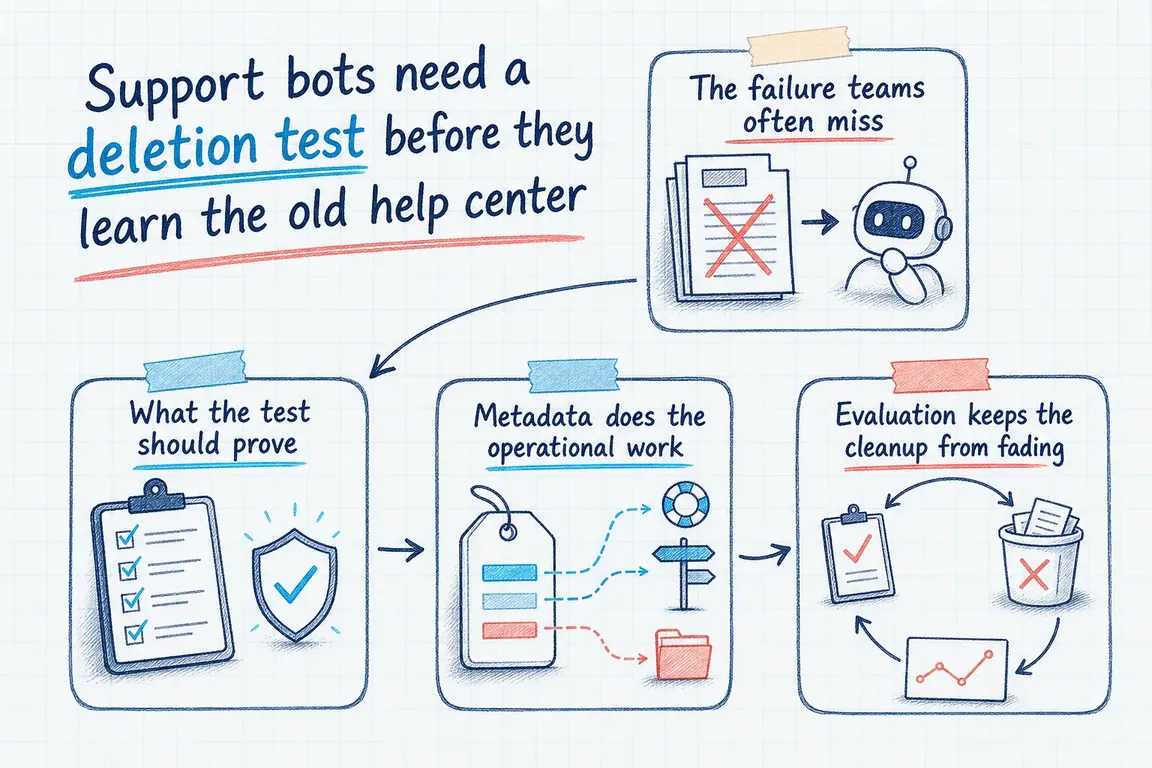
That is why deletion should be an acceptance test, not an assumption. Before approving a support bot for production, ask the delivery team to demonstrate that the complete system can forget one real article through the normal editorial workflow.
Removing a page is not the same as removing its knowledge
Retrieval-augmented generation usually does not train the underlying language model on each help article. Instead, an ingestion process creates searchable records from the source. One article may become many chunks, and those chunks may be copied into more than one index.
The connector therefore needs an explicit way to recognise a deletion and remove every derived record. Microsoft’s Azure AI Search documentation makes the distinction clear: change detection is built into its Azure Storage indexers, but deletion detection requires a configured soft-delete strategy. Microsoft also warns that the policy should be present from the first indexer run; adding it later can leave previously deleted documents behind.
Other platforms expose direct deletion operations. Pinecone, for example, supports deleting records by ID or metadata filter. That capability is useful only when your integration has retained a reliable ID or metadata value that connects every chunk to its source article.
| Checkpoint | Passing evidence | Common failure |
|---|---|---|
| Help center | The article is unpublished or marked inactive | The public page disappears but remains in an export feed |
| Ingestion | The sync records the stable source ID as withdrawn | The connector processes additions and edits only |
| Search layer | No active chunks remain for that source ID | Only one of several chunks is removed |
| Answer layer | Fresh sessions neither use nor cite the article | A cache or secondary index still supplies the answer |
| Operations | The removal completes inside an agreed time limit | The team accepts “eventually” without a deadline |
| Regression testing | The scenario runs before later releases | The incident is fixed once but never tested again |
Run one deletion through the real production path
Choose a low-risk article with a distinctive answer. Record its canonical URL, source ID, locale, publication status, owner, and last-modified value. Ask a question that reliably retrieves it, then save the answer, citations, retrieved passages, record IDs, and trace data as your baseline.
Next, unpublish the article using the same workflow your content team will use after launch. Do not manually tidy the vector database unless that is genuinely the production process. Trigger or wait for the normal sync, then verify each layer:
- Confirm that the CMS and its export or API report the article as inactive or deleted.
- Inspect the ingestion log and prove that the connector noticed the lifecycle change.
- Query the search index or vector store using the stable source ID, not merely the title.
- Check every relevant namespace, locale, staging copy, cache, and secondary index.
- Repeat the original question in a fresh conversation and inspect the retrieved sources.
- Try several paraphrases, including wording copied from the withdrawn article.
The test passes only when the old source contributes no passages, facts, or citations. One empty search result is not enough if another retrieval route can still find the material.
Give every chunk a traceable identity
Deletion is much easier when derived records carry lifecycle metadata. At minimum, retain a stable source ID, canonical path, locale, product area, publication status, source version or modification time, and responsible content owner.
Do not use the page title as the identifier; titles change. Do not assume that deleting one record removes an entire article; chunking often creates several records. Prefer deletion by known IDs when possible, or use an exact metadata filter tied to the stable source ID.
Platform-specific limits also matter. Microsoft notes that its soft-delete policies do not cover certain one-to-many indexing scenarios, which require an explicit index deletion request. Pinecone documents eventual consistency, so a short delay may occur before changed records are reflected in queries. Convert those technical details into a business rule: for example, withdrawn content must become unavailable within the agreed number of minutes, with an alert if it does not.
Decide what the bot should say afterwards
Forgetting a source does not mean the bot must become useless. It can answer from an approved replacement, explain that the information is no longer available, or route the customer to a person. The right response depends on the risk.
For a retired procedure, direct customers to the current workflow. For a withdrawn policy with no approved replacement, escalation is safer than a plausible improvisation. Write the expected fallback into the test so support, content, and engineering agree on what “correct” means.
This serving-path test is not the same as legal erasure. If personal or regulated data is involved, logs, backups, conversation histories, analytics tools, and provider retention policies may require a separate review.
Make deletion part of normal operations
Add withdrawn policies, replaced instructions, archived files, and renamed products to a small regression dataset. Run those cases before releases and monitor production traces for stale citations. LangSmith’s current evaluation model reflects this useful split: offline evaluations cover unit and regression testing before deployment, while online evaluations monitor real production behaviour.
Ownership should be equally explicit. Content decides when a source is invalid. Engineering owns propagation through the pipeline. Support defines the customer-facing fallback. Operations watches the deletion deadline and keeps evidence that the test passed.
A dependable support bot is not simply a model connected to a folder of articles. It is a managed content system with publication rules, withdrawal rules, traceable records, measurable deadlines, and accountable owners. If you need help turning those requirements into a practical delivery plan, Greg can help scope and manage the work.
Related on GrN.dk
- Your AI Workflow Needs an Acceptance Test Before It Meets Customers
- Google’s AI Search toggle needs a test plan, not a gut decision
- MCP 2026-07-28 Is an Auth Migration, Not a Version Bump
Need help with this kind of work?
Plan your support bot project with Greg Get in touch with Greg.