By Greg Nowak. Updated 25 October 2026.
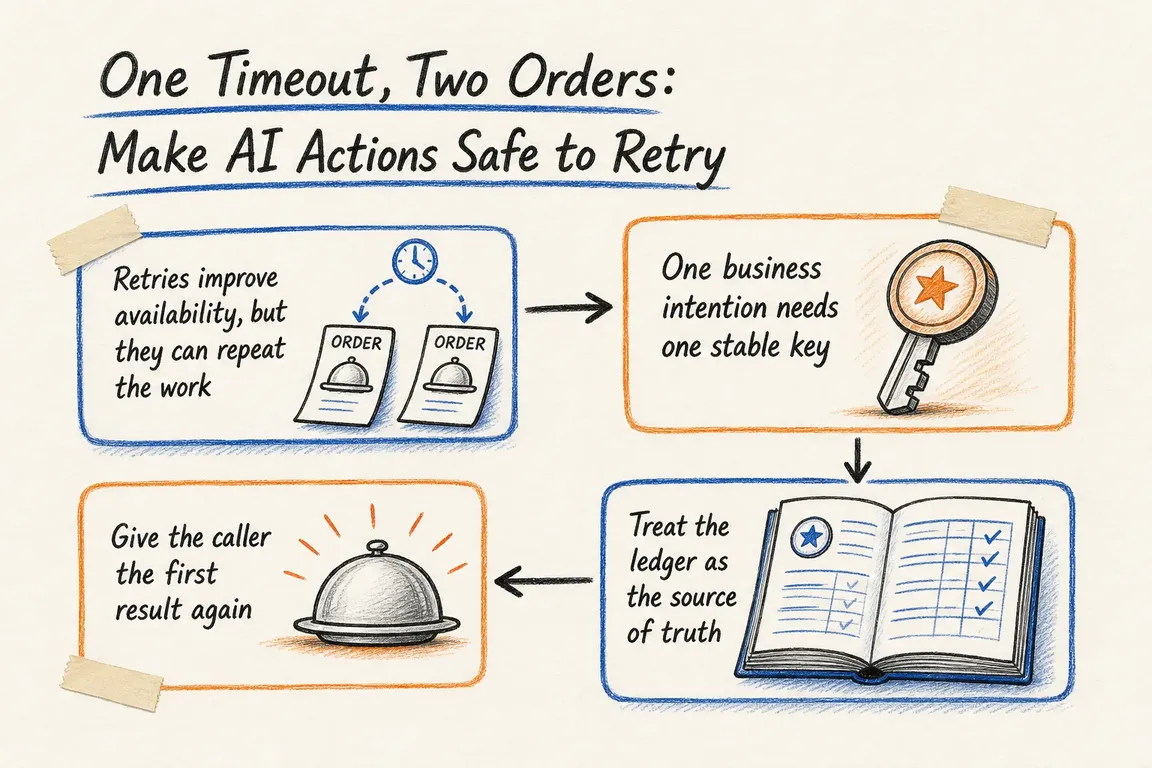
An AI agent places an order. The supplier accepts it, but the response disappears during a network timeout. The agent tries again. Without the right safeguards, your team now has two orders and a cancellation to arrange.
The same problem affects invoices, customer emails, CRM records and fulfilment jobs. A timeout means the caller did not receive an answer; the action may still have succeeded. Making AI actions safe to retry requires a persistent identity for each business instruction, a record of what happened and a recovery process for uncertain outcomes.
Start with what a duplicate would cost
Before changing retry settings, list the actions your automation can perform. Ask what happens if each runs twice. This gives business owners and delivery teams a practical way to prioritise integration work.
| Action | Safe retry behaviour | Safeguard to require |
|---|---|---|
| Read account or product data | Repeat within an agreed limit | Backoff, jitter and a deadline |
| Create an invoice or CRM record | Return the original record | Stable action key and stored result |
| Place an order or send a message | Avoid repeating an accepted request | Provider idempotency and outcome checks |
| Receive a webhook | Accept duplicate delivery without repeating work | Durable event receipt and an idempotent worker |
| Start a slow job | Return the existing job’s status | Persistent job ID and status lookup |
Give each business instruction a stable identity
An idempotency key identifies an action so repeated requests can resolve to the same result. Create and persist it before the first attempt, then reuse it across retries, worker restarts and agent sessions. Generating a new UUID inside the retry loop defeats the protection.
The integration should control this identity. Repeated model tool calls for the same approved purchase must resolve to the same action record. A prompt asking the agent to “avoid duplicates” cannot enforce that.
Store a fingerprint of the material request: amount, recipient, products and destination. Reject a reused key with changed data. A changed instruction needs a new identity, but resolve any uncertain earlier action before submitting its replacement. Keep sensitive customer data out of keys.
Check the provider’s actual retry contract
“Supports idempotency” leaves several questions unanswered: which endpoints, which responses, and for how long?
Stripe’s documentation distinguishes API v1 from v2. In v1, once execution begins, the first response is stored, including a 500; keys may be pruned after at least 24 hours. API v2 can retry failed or partially failed work and return an updated response. Match your recovery logic to the API you use.
LINE’s supported messaging endpoints require the retry key on the first attempt. An already accepted request returns 409, and keys remain valid for 24 hours. Acceptance does not guarantee message delivery. Treat these as provider-specific rules, not universal HTTP behaviour.
Keep a durable action ledger
Record the action key, operation, request fingerprint, workflow ID, status, timestamps, attempts, provider reference and result in a database. Require a non-null key and enforce uniqueness. For an existing PostgreSQL ledger table, the basic claim pattern is:
CREATE UNIQUE INDEX action_ledger_key_uq
  ON action_ledger (idempotency_key);

INSERT INTO action_ledger
  (idempotency_key, operation, request_hash, status)
VALUES
  (:key, :operation, :request_hash, 'processing')
ON CONFLICT (idempotency_key) DO NOTHING
RETURNING idempotency_key;
The placeholders are application-bound parameters. PostgreSQL’s INSERT documentation explains conflict handling and that RETURNING reports rows actually inserted. A returned row identifies the successful claimant; no row means the application must read the existing action in a subsequent query.
Commit the claim before calling the provider. Return the saved resource ID when complete, or report that processing continues. Avoid separate “check, then insert” logic: concurrent workers can both pass the check. This claim prevents competing initial submissions; it does not settle what happened after a worker crashed.
What should happen when the outcome is unknown?
A worker can submit an order successfully and crash before saving the response. Your local ledger then shows an unfinished action that already exists at the supplier.
Use the original provider key within its documented retention window, or query a unique business reference. If neither can establish the outcome safely, mark it outcome_unknown and stop automatic submission. An expired key is a reason to reconcile, not permission to start again.
Give operations a named owner and enough context to investigate: intended action, timestamps, provider references and lookup results. A stale processing record needs investigation; age alone does not prove failure.
Make webhook handoffs durable too
Stripe’s webhook guidance covers duplicate deliveries, asynchronous processing and events arriving out of order. Track event IDs, but also consider whether separate events represent the same business action. Avoid blanket deduplication by object ID: one object can have several legitimate changes.
Verify the signature, persist the event in a durable inbox with a unique event identity, then acknowledge promptly. Have a worker process pending inbox entries. If you use a separate queue, make publishing recoverable: recording an event as handled before successfully enqueuing it can silently lose work. The eventual business action still needs its own duplicate protection.
Test success followed by silence
Ask your delivery team to demonstrate these cases before enabling consequential actions:
- The supplier accepts an order, drops the response, and receives a retry.
- Two workers submit the same key simultaneously.
- A worker crashes after submission but before recording completion.
- A key is reused with changed data or after provider retention expires.
- Webhooks arrive twice, out of order, or during a queue outage.
Check the actual orders, messages and records created, alongside logs linking each workflow, key, attempt and final outcome.
Start with one consequential workflow
Choose purchasing, billing or outbound communication. Document its action identity, provider guarantees, stored result and reconciliation owner. That creates a concrete review scope for your internal team or agency.
Greg can help map these failure points and turn them into an implementation plan your team can maintain. Get in touch to review a workflow where duplicate actions would hurt.
Related on GrN.dk
- When the AI API Says “Try Again,” What Does Your Customer See?
- Not Every AI Job Needs an Instant Answer: Batch the Backlog
- OpenAI’s Agents API Is Durable. Is Your Workflow Recoverable?
Need help with this kind of work?
Review your AI workflow’s retry safeguards with Greg Get in touch with Greg.