By Greg Nowak. Last updated 2026-09-04.
A polished AI demo proves that a workflow can work. It does not prove that the workflow will behave reliably when customer language is ambiguous, a tool returns incomplete data, or somebody changes the model or prompt.
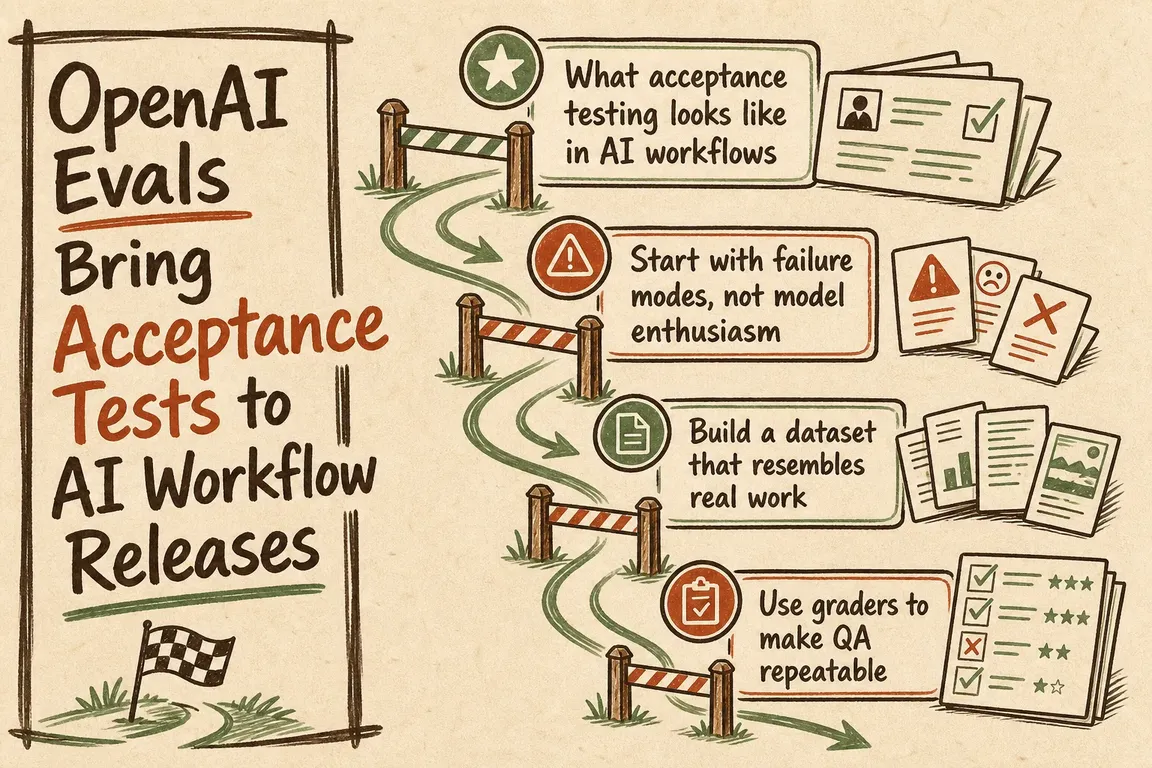
That distinction matters once AI starts drafting customer replies, classifying requests, updating records, or informing operational decisions. At that point, every release needs evidence—not another round of “the examples looked good.” OpenAI’s current evaluation guidance provides a useful foundation: define the expected behaviour, test it against representative cases, score the results, and repeat the process whenever the workflow changes.
Test the workflow contract, not only the prompt
An AI workflow is more than its main instruction. Its effective contract includes the prompt, model configuration, available tools, routing rules, output schema, validation checks, and escalation path. A harmless-looking change to any one of these can affect the others.
Start by writing down what the operation must be able to trust. For a support workflow, that could mean selecting the correct queue, preserving an account reference, refusing to invent missing information, and escalating sensitive cases. For a content workflow, it might mean using approved facts, following the requested format, and flagging claims that need review.
These requirements should become explicit test cases. OpenAI calls evals structured tests for measuring model performance and recommends task-specific evaluation over generic benchmarks. The useful question is not whether a model is broadly capable. It is whether this particular workflow meets your release conditions.
What should an AI release gate contain?
| Requirement | Suitable check | Release decision |
|---|---|---|
| Required fields, labels, or tool names | Exact or rule-based check | Block the release if mandatory data is missing or wrong |
| Correct routing and tool arguments | Expected tool and argument checks | Review failures that could send work or data to the wrong place |
| Useful, accurate written output | Clear rubric with human-calibrated model grading | Compare the candidate against the current production version |
| Ambiguous, hostile, or malformed input | Adversarial cases and human review | Require safe failure, clarification, or escalation |
| Previously observed production failure | Permanent regression case | Do not reintroduce a problem the team has already fixed |
There is no universal acceptable score. A drafting assistant that always receives human review can tolerate different failure modes from a workflow that triggers an action automatically. Set thresholds according to the consequence of failure, and treat a critical check as a hard gate rather than hiding it inside an average score.
Build the test set from real work
A useful dataset resembles the traffic the workflow will actually receive. Begin with ordinary examples, then add awkward cases: incomplete context, contradictory instructions, unexpected formatting, long histories, multilingual input, near-duplicate categories, and unavailable tools. Include adversarial cases when users or external content could try to override the workflow’s instructions.
OpenAI recommends combining production data, historical data, domain-specific examples, and human-curated cases. Its guidance also stresses typical, edge, and adversarial cases. That is a practical argument for logging during a pilot: traces and reviewer corrections are raw material for the acceptance suite.
Each case should record the input, relevant context, expected outcome, scoring method, and business importance. Teams using the OpenAI Evals API can supply structured test data, including JSONL datasets with human-provided reference labels. Keep a separate held-out set where practical so repeated prompt tuning does not merely optimise for familiar examples.
Match the grader to the decision
Use deterministic checks wherever the answer really is deterministic. OpenAI’s graders support string checks for straightforward pass-or-fail requirements, text-similarity checks for comparison with a reference, score-model graders for rubric-based judgment, and Python graders for custom logic. Tool calls can be evaluated by checking the selected function and its arguments separately.
Do not ask a model judge to decide whether an exact identifier is correct when code can do that reliably. Conversely, exact matching is a poor measure of whether a customer reply is accurate, complete, and appropriately cautious. For qualitative output, create a short rubric with examples of passing and failing work.
Human review remains the calibration layer. OpenAI describes human evaluation as high quality but slow and costly, while model-based grading is more scalable. Before using an automated judge as a release gate, check that its decisions agree with trusted human labels. Revisit that agreement as the dataset and workflow evolve.
Red-team the paths ordinary QA will miss
Normal evals ask whether the workflow behaves as intended. Red teaming asks how it behaves under abusive, conflicting, or unexpected input. OpenAI positions adversarial testing as complementary to evals because routine quality checks may not expose misuse and high-risk interactions.
For an internal workflow, this can be quite concrete: place hostile instructions inside a document, omit a required identifier, request an action outside the user’s authority, return malformed tool data, or make the correct downstream system unavailable. The expected result may be a refusal, clarification request, safe fallback, or human escalation—not a clever answer.
Make evaluation part of every release
The strongest acceptance suite keeps learning. OpenAI’s agent-improvement example turns traces and human or model feedback into rerunnable evals, then places a validation gate over the current behaviour. That is the right operating model for prompt, model, tool, and routing changes: baseline the current version, run the candidate against the same suite, inspect critical failures, and release only when the evidence supports it.
A sensible first implementation does not need hundreds of cases or a complicated agent architecture. Start with the decisions that could create costly rework, customer harm, or bad data. Add every meaningful production failure to the regression set. Over time, the suite becomes a record of what the business has learned—not merely a technical scorecard.
Turn the pilot into a controlled release
If your AI workflow is moving beyond a demo, I can help map its failure modes, assemble a focused eval dataset, choose appropriate graders, and establish a practical release gate. Talk to Greg about your AI workflow.
Related on GrN.dk
- Your AI Workflow Needs an Acceptance Test Before It Meets Customers
- When AI writes JSON, one bad field can break the workflow
- A Voice Agent Is Only Ready When the Human Handoff Works
Need help with this kind of work?
Plan a safer AI workflow release Get in touch with Greg.