By Greg Nowak. Updated 29 September 2026.
An NGINX upgrade can look routine until an older application starts failing only after a quiet period, or a login flow behaves differently under concurrent use. NGINX 1.30 changes how its default HTTP proxy connection to a backend works: it uses HTTP/1.1 and keeps upstream connections available for reuse. Most applications should benefit, but inherited configuration and unusual backends deserve a deliberate check.
For a business owner or agency team, this is a manageable compatibility review, not a reason to delay every upgrade. Identify which applications sit behind NGINX, test the journeys that matter, and agree who will make the rollback call. As of 29 September 2026, NGINX lists 1.30.5 as its current stable release; check your package vendor’s history when planning the actual update.
What changed in NGINX 1.30?
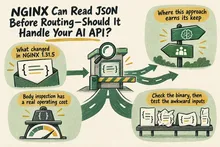
The new defaults arrived in mainline version 1.29.7 and carried into the 1.30 stable branch. proxy_http_version now defaults to 1.1 instead of 1.0. Upstream keep-alive caching is enabled by default, equivalent to keepalive 32 local;. That can reduce repeated connection setup between NGINX and an HTTP backend.
The number 32 is the maximum number of idle upstream connections cached per worker process. It does not limit active or total backend connections. If you are sizing a backend, consider the worker count, peak traffic and the backend’s own connection limit rather than treating 32 as a safety cap.
| Backend or configuration | First action | Test that matters |
|---|---|---|
| Modern HTTP application | Keep the new defaults | Response times, 5xx rates and backend connections |
| Older or vendor-managed application | Test reuse before rollout | Login, uploads and the first request after an idle period |
| NTLM or Negotiate authentication | Review connection-bound authentication setup | Concurrent sessions and re-authentication |
Explicit keepalive 32; |
Decide whether reuse across locations is intended | Routes that reach the same upstream address |
| Backend proven to need fresh connections | Make a route-specific exception | Reproduce the fault, then retest the fix |
Audit the configuration NGINX actually loads
Start with the running build and the complete loaded configuration. A shared include, hosting panel or deployment template can affect a route even when its local file looks straightforward. These commands help locate the relevant settings:
sudo nginx -V
sudo nginx -T 2>&1 | grep -nE 'proxy_pass|proxy_http_version|proxy_set_header[[:space:]]+Connection|keepalive|ntlm'
sudo nginx -t
nginx -V shows build options; nginx -T tests and prints the configuration, including included files. Keep its output within your operations team because it may reveal internal addresses or other sensitive settings. The search is a starting point: follow each proxy_pass route to its upstream and record the application owner, especially where several clients share an NGINX instance.
Review proxy_set_header directives together. NGINX inherits them from a parent level only when the current level defines none. Adding one header inside a location can therefore replace a larger inherited set. Check the effective headers before removing an old Connection line or adding an exception.
Keep configuration changes small and intentional
Older configurations often contain proxy_http_version 1.1; and proxy_set_header Connection ""; solely to enable upstream reuse. NGINX says those lines are no longer needed for that purpose. They can remain while you validate the upgrade; remove redundant lines later through a reviewed change, particularly if a shared include serves several applications.
An explicit keepalive 32; needs a closer look. Without local, a cached connection can be reused across locations that reach the same upstream address. The new implicit default keeps those caches local to each location. If that separation is what you want, express it clearly in the upstream block:
upstream application_backend {
    server 127.0.0.1:8080;
    keepalive 32 local;
}
Do not tune keep-alive request counts or timeouts just because the directives exist. First establish whether the backend has a documented limit, whether sockets are under pressure, or whether a reproducible failure points to an idle connection issue.
Test awkward backends on real user journeys
A homepage check will miss many compatibility faults. Exercise sign-in and sign-out, simultaneous users, administrative actions, larger uploads and the first request after the backend has sat idle. Compare application logs with NGINX errors and response timings. For NTLM or Negotiate, inspect how authentication is bound to upstream connections and test with concurrent sessions; do not assume a single successful login proves the setup is safe.
If testing shows that one backend truly requires HTTP/1.0 and a closed connection, contain the change to its route:
location /legacy-app/ {
    proxy_pass http://legacy_backend;
    proxy_http_version 1.0;
    proxy_set_header Connection "close";
}
Document why the exception exists, who owns the backend and what would allow its removal. A server-wide downgrade would also discard reuse for applications that work well with the new defaults.
Roll out with evidence and a way back
Before the upgrade, capture a short baseline: 502 and 504 rates, upstream connection and response times where logged, authentication failures, backend connection counts and relevant application errors. Test the higher-risk routes first, then canary production traffic if your setup permits it. Agree on a monitoring window and a stop condition, such as a sustained rise in backend errors or a failed critical login journey.
Keep the previous package and configuration deployment path available until the checks pass. The useful handover is an application inventory, the configuration decisions, test results, monitoring ownership and a rollback procedure. If your team is juggling inherited client setups and vendor systems, Greg can help plan and coordinate the upgrade.
Related on GrN.dk
- Nginx 1.30 Changed Upstream Connections: What to Test Before You Upgrade
- Agentic AI: What It Is, How It Works, and When to Use It
- Before You Buy a GPU: Test Your Team’s Local AI Workload
Need help with this kind of work?
Plan your NGINX upgrade with Greg Get in touch with Greg.