By Greg Nowak. Last updated 2026-07-18.
When a business asks to automate intake, the visible problem is usually the messy input: emails, PDFs, forms, support tickets, copied notes, or documents supplied by customers. The tempting response is to start writing prompts. That is rarely the best place to start.
Structured Outputs make it substantially easier to obtain JSON that follows a defined schema. This removes an important source of production failures, but it does not remove the harder operational questions. What should the canonical record contain? What counts as missing? Which values may be inferred? When should a person review the result? And what is allowed to write into the CRM, ERP, or case-management system?
In other words, the work has shifted. A reliable intake project is now less about persuading a model to produce roughly the right shape and more about designing a trustworthy data contract around it.
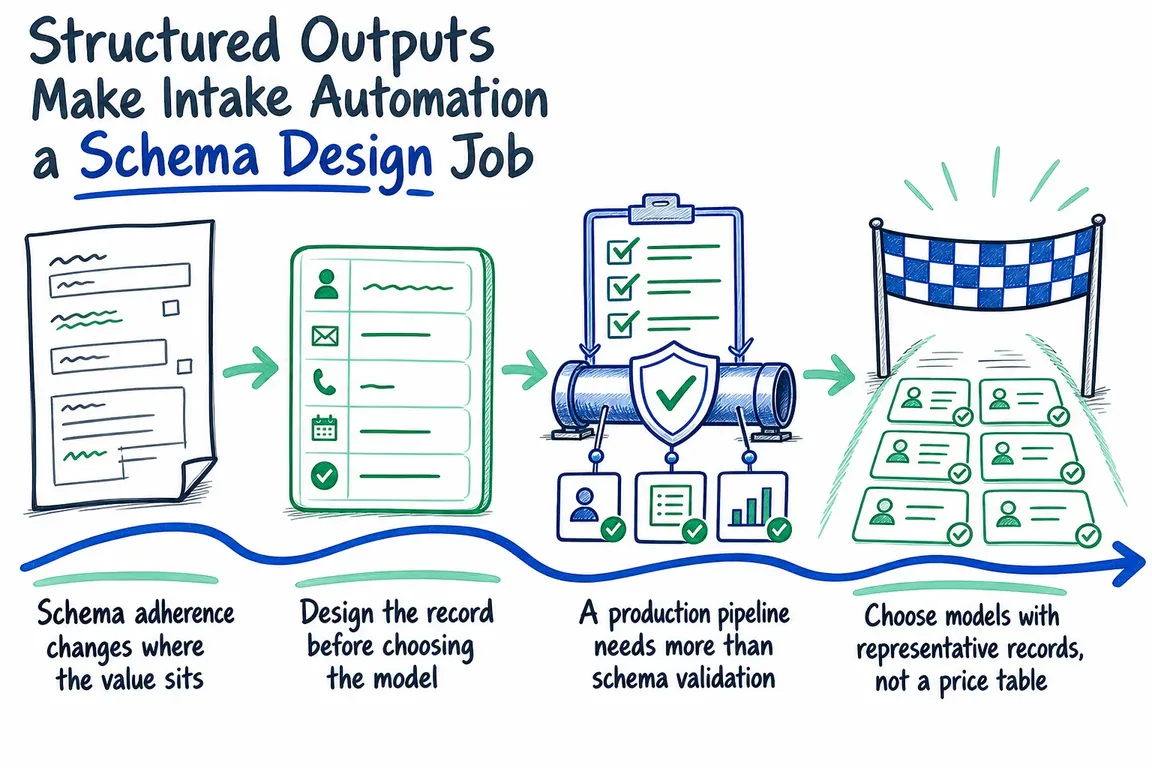
Schema adherence changes where the value sits
JSON mode and Structured Outputs are not interchangeable. JSON mode helps produce valid JSON, while Structured Outputs are designed to make the response adhere to a supplied schema. OpenAI recommends Structured Outputs where the selected model and use case support them.
That distinction matters commercially. Valid JSON can still contain missing keys, unexpected nesting, inconsistent field names, or values that downstream software cannot accept. A strict schema removes much of that structural uncertainty. The valuable work then moves upstream into record design and downstream into validation, exception handling, and integration controls.
For an operations team, the deliverable should therefore be a controlled intake pipeline—not merely a prompt and an API call. For an agency, this is also a better project boundary: schema versions, acceptance criteria, review rules, and system ownership are tangible items that can be agreed with the client.
Design the record before choosing the model
Start with the record the receiving system needs. Give every field a precise meaning, type, permitted values, and owner. Resolve disagreements such as whether “customer” means the purchaser, account holder, or end user before asking a model to populate the field.
OpenAI supports a subset of JSON Schema, so an existing enterprise data model may need simplifying. The root must be an object rather than a top-level anyOf. Fields must be marked as required; when a value may legitimately be absent, model that state explicitly with a nullable type. Strict function schemas also require additionalProperties: false on each object.
Do not use an empty string, zero, or “unknown” interchangeably. A useful intake schema distinguishes at least three situations: the source explicitly supplied a value, the value was not present, and the source was too ambiguous to decide. That distinction makes review queues and reporting far more useful.
| Workflow need | Recommended pattern | Operational control |
|---|---|---|
| Normalize content for another processing step | Structured text.format |
Validate business rules before accepting the record |
| Call an internal service or create a record | Strict function calling | Authorize and execute the action in application code |
| Process routine, high-volume material | Lower-cost model proven by an eval | Escalate low-confidence or invalid cases |
| Handle ambiguous or high-impact records | More capable model or human review | Require approval before consequential writes |
A production pipeline needs more than schema validation
A sensible implementation separates extraction from action:
- Capture the original input. Keep the source document, message, identifiers, and arrival time so the result can be audited.
- Extract into a versioned schema. Record which prompt, schema, and model produced the output.
- Apply deterministic checks. Validate dates, identifiers, totals, permitted statuses, cross-field dependencies, and duplicate rules in ordinary application code.
- Route exceptions. Send incomplete, contradictory, refused, or truncated responses to a retry path or human queue.
- Write through a controlled integration. Use permissions, idempotency, logging, and approval rules appropriate to the cost of a bad update.
Function calling is appropriate when the model needs to request an operation in your system. The application still owns the actual execution. Enable strict: true, and consider parallel_tool_calls: false when a turn should produce no more than one auditable tool call. That setting is a workflow decision, not a substitute for authorization.
Choose models with representative records, not a price table
OpenAI’s current model catalog presents GPT-5.6 Sol for complex work, Terra as the intelligence-and-cost balance, and Luna for cost-sensitive volume. Those labels are a starting point, not proof that a model suits your intake.
Build a test set from representative, properly handled records, including poor scans, missing fields, conflicting statements, unusual layouts, and genuinely ambiguous cases. Define ground-truth outputs and graders, then compare field accuracy, exception rates, latency, and cost. Re-run the evaluation when the schema, prompt, model, or source mix changes.
A useful routing design may send routine records through an economical model while escalating harder cases. However, routing should be based on measured performance and business impact—not on an untested assumption that every long document needs the most expensive option.
Structure is not the same as truth
A perfectly shaped record can still contain the wrong customer number, an invented date, or a confident interpretation of ambiguous text. OpenAI’s guidance explicitly notes that Structured Outputs can still contain mistakes. Schema adherence is therefore necessary for dependable automation, but it is not an accuracy guarantee.
Before launch, agree who owns the schema, which fields may be inferred, what triggers review, how corrections feed back into testing, and which actions require approval. Those decisions determine whether the automation becomes dependable infrastructure or simply moves cleanup work somewhere less visible.
Planning an intake automation project?
Greg can help map the sources, design the data contract, choose and evaluate the model path, and connect the result to the systems your team already uses. Discuss the workflow with Greg before committing it to production.
Related on GrN.dk
- When AI writes JSON, one bad field can break the workflow
- AI automations need a spend dashboard before the first runaway bill
- A Voice Agent Is Only Ready When the Human Handoff Works
Need help with this kind of work?
Plan your intake automation with Greg Get in touch with Greg.