By Greg Nowak. Updated 3 November 2026.
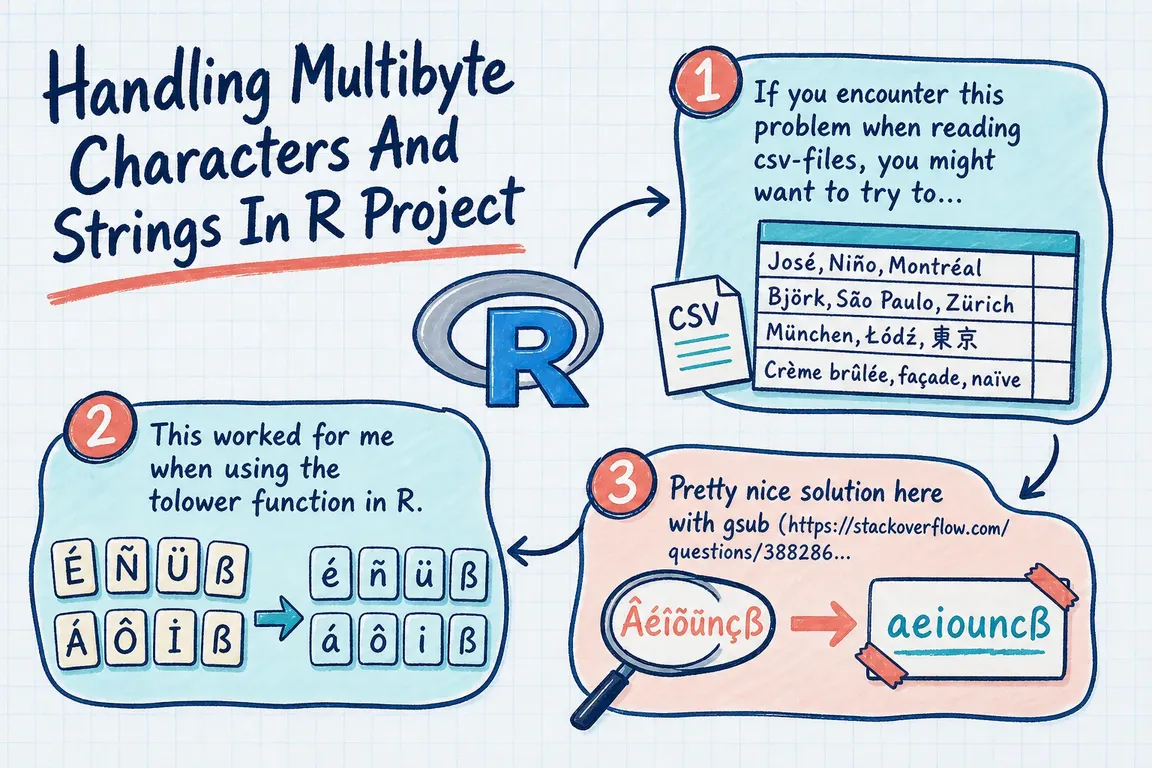
A customer CSV imports into R, the rows appear, and everything looks ready. Then tolower() stops with an “invalid multibyte string” error. For an operations team or agency preparing a delivery, the immediate temptation is to remove whatever characters caused the failure.
That can leave you with a report that runs and customer names that are wrong. Danish letters such as æ, ø and å, accented product names and international addresses are part of the data.
The reliable approach is to confirm the source encoding, import the original file correctly, and check representative records before applying text transformations. Here is how to do that without turning a technical fix into a data quality problem.
What causes an invalid multibyte string error?
An encoding defines how bytes represent characters. UTF-8 can use several bytes for one character. If those bytes are interpreted using the wrong encoding, or a file contains damaged or mixed text, a later string operation may fail.
Start by finding where the problem first appears. Keep an untouched copy of the export so you can repeat the investigation.
| Symptom | Likely investigation | Next step |
|---|---|---|
| Names look wrong immediately after import | Incorrect decoding | Confirm export settings and reimport the original file |
| A string operation fails on particular records | Invalid bytes or inconsistent encoding | Isolate those records and compare with the source |
| Only one supplier’s exports fail | Different export conventions | Document an import configuration for that supplier |
| The receiving system requires ASCII | A destination restriction | Create a separate export field and review character loss |
Confirm the encoding before changing the import
Ask the exporting system’s owner which encoding it writes. Use the declared value, whether that is UTF-8, Windows-1252 or another encoding. Windows-1252 and Latin-1 are not interchangeable specifications.
If nobody knows, readr::guess_encoding("customers.csv") can suggest candidates. Treat the result as a clue. The readr locale documentation demonstrates that a plausible guess can produce valid text with incorrect letters. Compare names, punctuation and symbols against known originals before accepting an encoding.
Read the CSV with an explicit encoding
For a file path, base R’s fileEncoding argument enables conversion during import. The similarly named encoding argument declares an encoding without re-encoding the input. This distinction matters when copying fixes from another project; see R’s data input reference.
# Set this from the confirmed export specification.
source_encoding <- "UTF-8"

df <- read.csv(
  "customers.csv",
  fileEncoding = source_encoding,
  colClasses = "character"
)
Reading columns as text preserves leading zeros in identifiers while you investigate. Convert dates and numbers deliberately afterwards. For semicolon-separated files with decimal commas, use read.csv2().
Base R’s file conversion targets the current locale, which may limit the characters it can represent. If the project already uses readr, specify the source encoding there; its import functions return UTF-8 strings:
df <- readr::read_csv(
  "customers.csv",
  locale = readr::locale(encoding = source_encoding),
  col_types = readr::cols(.default = readr::col_character())
)
These are alternative import approaches. Neither removes the need to inspect warnings and compare the imported values with the source.
Convert existing strings without hiding failures
Encoding(text) reports a string’s declared encoding. It does not detect the original file encoding, and "unknown" does not automatically indicate damage: ASCII strings are normally unmarked. Assigning Encoding(text) <- "UTF-8" changes the declaration rather than converting the bytes, as R’s encoding reference explains.
Use iconv() when a vector contains bytes in a known source encoding. This example deliberately constructs a Latin-1 name:
text <- c("S\xf8ren", NA_character_)
converted <- iconv(
  text, from = "latin1", to = "UTF-8", sub = NA
)

failed <- which(!is.na(text) & is.na(converted))
if (length(failed) > 0L) {
  stop("Encoding conversion failed; review the original values.")
}
The check separates new conversion failures from existing missing values. Avoid sub = "" during diagnosis because it discards unconvertible bytes. Conversion behaviour varies across platforms, and success does not prove the source encoding was correct; see R’s iconv documentation.
Do not apply this Latin-1 conversion to text already imported correctly as UTF-8. If the import was wrong, return to the original file. Converting already garbled text can compound the problem.
Apply lowercase and ASCII rules separately
After correcting the input, preserve the display name and create a separate lowercase field. Replace customer_name with your actual column name:
df$customer_name_lower <- tolower(df$customer_name)Case conversion depends on the platform and locale, according to R’s case conversion documentation. Check the languages you process on the machine running the scheduled job. A lowercase name alone should not serve as a customer identifier.
If a destination explicitly permits only printable ASCII, this command remains useful on correctly decoded text:
df$customer_name_ascii <- gsub(
  '[^\x20-\x7E]', '', df$customer_name
)
It deletes everything outside ASCII space through tilde, including accented letters, emoji, tabs and line breaks. “Søren” becomes “Sren”. That is deletion, not transliteration. Keep the result separate and agree acceptable changes with whoever owns the receiving system.
Make the next import predictable
Before releasing an import, reconcile record counts, review warnings and unexpected missing values, and inspect examples containing international characters. Keep those examples as repeatable checks. Document the encoding, delimiter and expected columns for each source, along with who resolves failed deliveries.
If CSV problems keep delaying reporting or client work, talk to Greg about the import workflow. Share the failing command, export settings and an anonymised sample that preserves the problematic bytes. That gives us a practical starting point for fixing the immediate issue and making future imports dependable.
Related on GrN.dk
- Can’t Publish in WordPress? Fix the Invalid JSON Response Without Guesswork
- Drupal Deployments: Keep Small Fixes From Rewriting Live Settings
- Logistics Optimization in 2026: Fix the Flow Before You Buy More Tech
Need help with this kind of work?
Talk to Greg about your CSV import workflow Get in touch with Greg.