By Greg Nowak. Updated 26 October 2026.
A Cloudflare Worker that forwards website enquiries to a CRM may contain very little code. If it stops, the sales team still loses enquiries. The size of the script tells you almost nothing about the importance of the dependency.
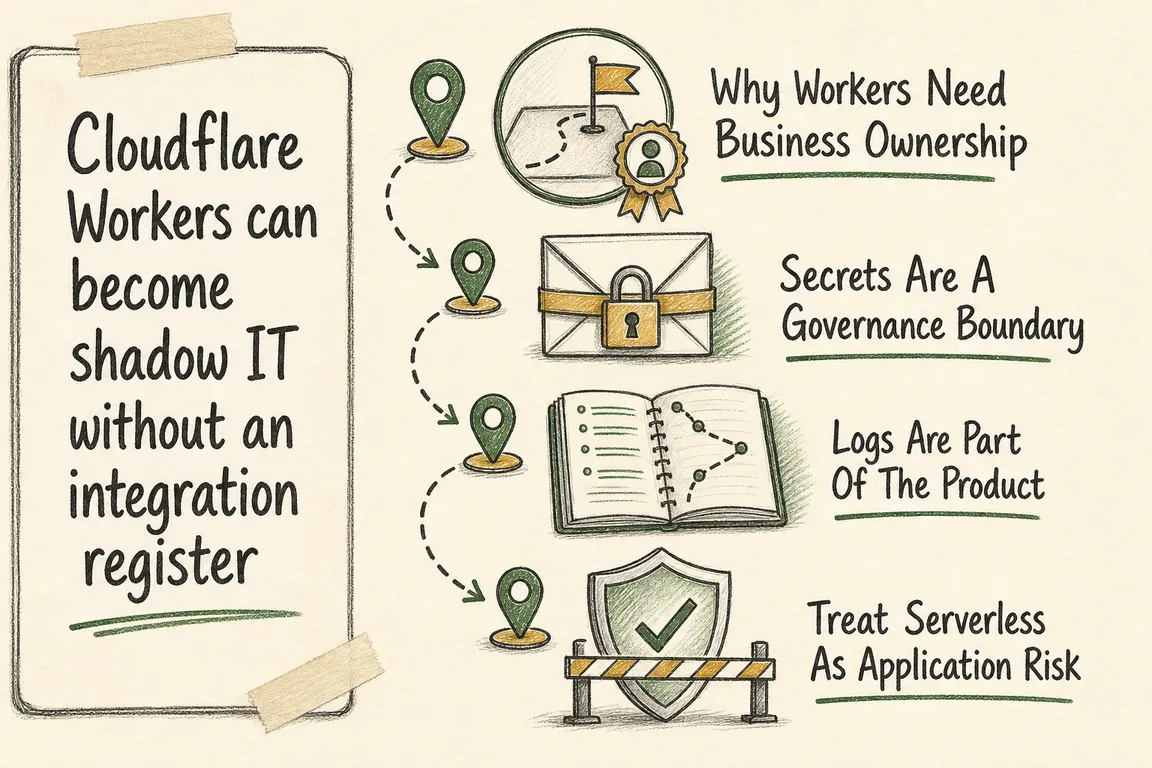
Workers become shadow IT when a business relies on them without knowing who maintains them, how failures are detected or how to recover. A practical integration register makes those responsibilities visible. Start with the Workers that affect leads, orders, payments or customer access.
Register the business workflow, then the Worker
Use a recognisable name such as “Website lead intake”, alongside the deployed name form-proxy-prod. Explain what breaks when it fails and how long the business can tolerate that interruption. Register anything that accepts external events, changes customer-facing behaviour, handles credentials or updates business records.
Record every entry point: HTTP endpoints, schedules, queues and calls from other Workers. For HTTP, distinguish Custom Domains, where the Worker is the origin, from Routes in front of an existing origin. Cloudflare recommends these for production rather than workers.dev. See its routing guidance.
A register your team can actually use
A shared document, spreadsheet or repository file is enough. Use one entry per workflow, linking its Workers and environments. The test is whether someone covering for the maintainer can find these answers.
| Area | What to record | Decision it supports |
|---|---|---|
| Purpose and priority | Workflow, business owner, failure impact, acceptable interruption | What needs attention first? |
| Entry points and dependencies | Account, Worker names, environments, routes, triggers, APIs and storage bindings | What else could a change affect? |
| Access and credentials | Secret names, purpose, rotation owner and approved access process; never values | Who can restore or revoke access? |
| Delivery | Repository, configuration, deployment process and technical maintainer | Can another person release a fix? |
| Failure handling | Logs, alerts, responder, retry rules and failed-event location | Will we notice and recover missing work? |
| Recovery and review | Known-good version, resource constraints, replay procedure and last verification date | Can we restore the workflow safely? |
Audit what is deployed before trusting the repository
Compare the Cloudflare account with your repositories. Look for dashboard edits, unfamiliar production names and deployments nobody can reproduce. Mark unknown ownership explicitly and assign someone to investigate.
From each Worker’s project directory, these read-only Wrangler commands provide a useful snapshot:
npx wrangler deployments list --json
npx wrangler deployments status --json
npx wrangler secret list --format json
The first lists the ten most recent deployments; the second shows the current deployment state. The third lists secret names and types without exposing values. Target the correct Worker with --name, or select a configured environment with --env. Check the Wrangler command reference for options. These commands are a starting point, not a complete account inventory.
Compare live routes, bindings, compatibility settings and observability with version control. Cloudflare recommends treating the Wrangler configuration as the source of truth. Sensitive values belong in secrets rather than plaintext vars. You can declare expected names in secrets.required; current Wrangler validates their presence during deployment. Presence does not prove a credential still works. See the configuration documentation.
Test what happens when the destination fails
For a lead-routing integration, trace a test enquiry through to its CRM record. Then test a timeout, an invalid credential and a duplicate delivery in a suitable test environment.
Write down when the Worker acknowledges receipt. Returning success before the destination accepts the event is safe only if there is a reliable way to retain and finish the work. Record where failed events wait, who handles them and how retries avoid duplicate records. A rollback cannot recover an enquiry that was never stored.
Make monitoring answer a business question
“Did this enquiry reach the CRM?” is more useful than “Did the Worker run?” Log a safe correlation identifier, event type, downstream status and elapsed time. Avoid full customer payloads and credentials.
Workers Logs indexes structured JSON fields and supports head-based sampling. Record whether logging is enabled, the sampling rate and the available retention. An absent log does not prove an event never arrived. For critical workflows, consider a separate reconciliation check between accepted events and completed business records.
Give every alert a named responder and a first action. Check who receives it when the agency contact or developer is away.
Check recovery beyond the rollback command
npx wrangler rollback can restore an earlier Worker version, but connected resources and their data do not roll back with it. Deleted resources referenced by bindings and certain Durable Object lifecycle changes can also prevent rollback. Review Cloudflare’s rollback limits before relying on an older version.
Record a known-good version and the resources it needs. Rehearse recovery after meaningful schema or binding changes, including how to reconcile missed or duplicate events. Define the business check that confirms recovery: a successful response alone is insufficient.
Make ownership survive the handover
Name a business owner who sets priorities and a technical maintainer who can diagnose and deploy. For agency work, agree who controls the account, repository, billing and support access before handover. Have the receiving team demonstrate that it can find the logs and follow the recovery procedure.
Update the register when dependencies change and review critical entries before staff or suppliers leave. Start with the highest-impact workflow, then work down the list.
If nobody can confidently explain your Workers setup, talk to Greg about a Cloudflare Workers review. He can help map dependencies, clarify ownership and prioritise maintenance so your team knows what needs attention next.
Related on GrN.dk
- One Timeout, Two Orders: How to Make AI Actions Safe to Retry
- When the AI API Says “Try Again,” What Does Your Customer See?
- Your AI Workflow Runs on One Person’s API Key. Now What?
Need help with this kind of work?
Talk to Greg about a Cloudflare Workers review Get in touch with Greg.