By Greg Nowak. Updated 10 October 2026.
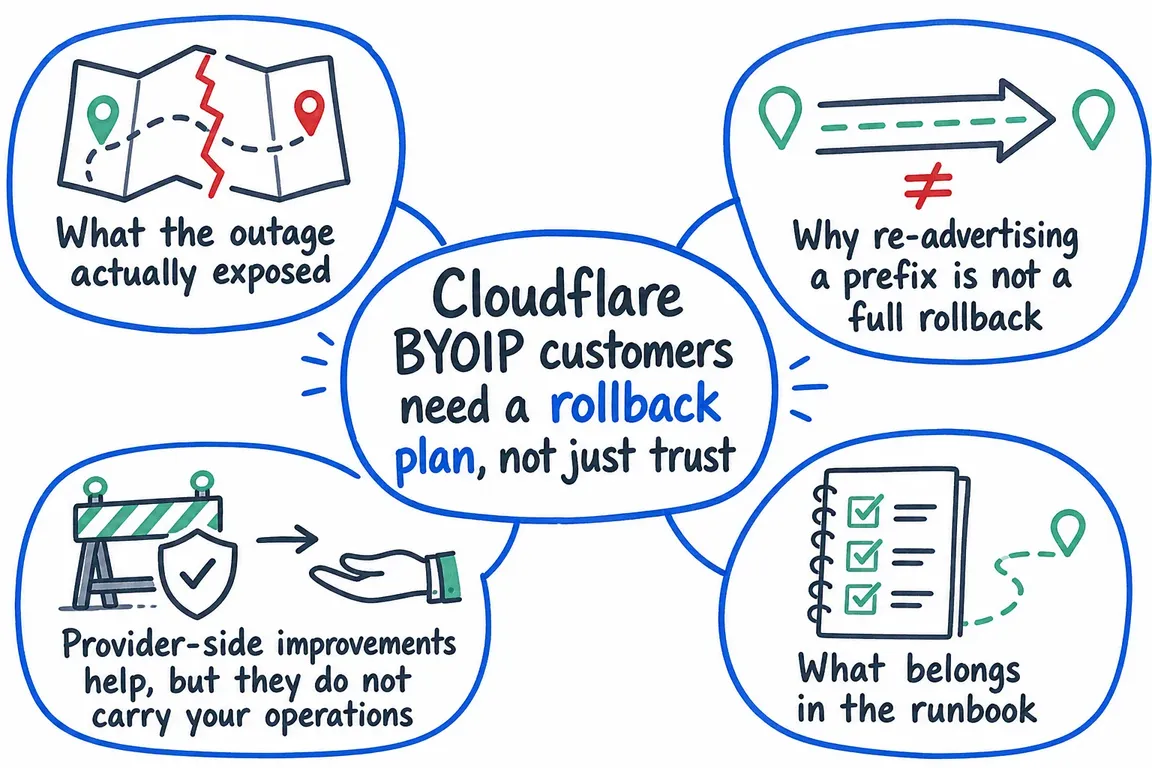
If your business uses Cloudflare Bring Your Own IP (BYOIP), keeping your IP addresses does not automatically give you a quick recovery path. A routing failure can make a website, application, or partner connection unreachable while the underlying servers are still running.
A useful rollback plan connects technical recovery to business decisions: which services matter most, what your team can restore, when Cloudflare must intervene, and whether an alternative path can actually serve customers. That is work an operations lead can organise with their network specialist and agency team before an incident.
What February's BYOIP outage taught customers
In its February 20, 2026 postmortem, Cloudflare attributed the outage to an internal change that unintentionally withdrew about 1,100 BYOIP prefixes. The incident lasted six hours and seven minutes; customers recovered at different points within that period.
Some customers could restore service by toggling advertisements. Others had lost service bindings as well as advertisements, and needed Cloudflare to restore configuration across its edge. The operational lesson is that restoring a route and restoring the service behind it are separate jobs.
Check routing and service configuration separately
A prefix is a block of IP addresses. BGP advertisement tells Internet networks how to reach that block. A service binding determines which Cloudflare product handles traffic for an address within it.
Cloudflare's service-binding documentation requires a default binding for the whole prefix and allows additional bindings for specific addresses or ranges. For example, Magic Transit can cover the prefix while selected addresses use CDN or Spectrum.
The same documentation says binding operations are API-only and that creating or deleting bindings takes four to six hours to propagate, with likely disruption for affected addresses. Treat binding changes as production changes with a maintenance window and recovery decision, rather than assuming they are an immediate repair.
| Observed condition | Recovery decision | Evidence to collect |
|---|---|---|
| Advertisement missing; bindings intact | Use the approved re-advertisement procedure after checking provider guidance. | Prefix ID, previous state, external route visibility, application checks. |
| Advertisement and some bindings missing | Identify affected ranges and escalate the configuration gap; returning routes may give partial recovery. | Expected bindings compared with current state, working and failing addresses. |
| Advertisement and all bindings missing | Escalate to Cloudflare early and assess a prepared fallback. | Saved configuration, affected services, account and prefix IDs. |
| Route visible; application still failing | Check service configuration and the application path before declaring recovery. | Connection tests, application responses, origin or tunnel health. |
Build a runbook someone else can execute
Start with one record per production prefix. Include its CIDR range, Cloudflare prefix ID, account owner, default binding, overrides, and the services that depend on it. Record egress dependencies too: a partner may accept connections only from your usual source addresses.
Keep a dated export of expected configuration somewhere accessible during an outage. For an agency, identify the client account and the person authorised to approve changes. For an internal team, name a primary operator and a backup, and verify their access before it is needed.
The procedure should specify:
- Diagnosis: compare external route visibility with advertisement state, bindings, and application health.
- Execution: record the approved dashboard or API steps, required permissions, and the exact prefixes in scope.
- Escalation: open a provider case promptly for missing bindings, blocked controls, or unexplained partial recovery.
- Communication: name the person responsible for customer updates and set the next update time.
Send support a compact evidence pack: UTC timestamps, account and prefix IDs, expected versus observed state, failed checks, and actions already taken. This gives the provider something specific to investigate and reduces repeated troubleshooting.
Allow time for recovery, and avoid repeated toggling
Cloudflare's dynamic-advertisement guidance gives typical enablement times of two to seven minutes and withdrawal times of approximately 15 minutes. It also requires at least 15 minutes between advertisement-status changes; earlier requests return a rate-limit error.
Write those intervals into the relevant procedure. An accepted change is a checkpoint. Confirm recovery with external routing observations and real application transactions from more than one network. Use a harmless test of the affected workflow, such as login or a partner connection, rather than relying only on a homepage response.
Make the fallback credible before you need it
For a planned Magic Transit cutover, Cloudflare's safe-withdrawal guidance recommends announcing the same-length prefix from the origin network, allowing convergence, verifying that traffic has drained, and then withdrawing Cloudflare's advertisement. It suggests typically five to ten minutes for convergence, while warning that external ISP behaviour varies.
This is a planned draining procedure, not a guaranteed rescue during a provider outage. Have a network specialist adapt it to your topology. Check routing authorisation in advance: IRR records and RPKI Route Origin Authorizations identify which networks may originate your prefixes.
Then test the service behind the alternative route. Does it have sufficient capacity, certificates, firewall rules, application routing, and protection? A CDN or Spectrum deployment needs its proxy functions accounted for. Moving an announcement alone does not recreate them.
Rehearse the decisions as well as the changes
Begin with a tabletop exercise covering a withdrawn prefix and missing bindings. Can the backup operator find the inventory, access the controls, and assemble a support case? Use a controlled maintenance window for any live cutover test, and record measured recovery time and unresolved dependencies.
Set a recovery target for each critical service. If the tested fallback cannot meet it, that is an architecture decision to address before the next incident.
If your BYOIP recovery plan needs coordination across a provider, network team, and agency, talk to Greg about organising the work. A practical starting scope is a dependency inventory, a reviewed runbook, and a rehearsal with clear owners.
Related on GrN.dk
- Cloudflare Page Rules Debt: How Quiet Configuration Drift Breaks Business Websites
- JavaScript-Heavy Service Pages Still Lose Leads: What to Audit in 2026
- Cloudflare’s Enforce DNS-Only Switch: Test Your Origin Before an Incident
Need help with this kind of work?
Plan your BYOIP recovery with Greg Get in touch with Greg.