By Greg Nowak. Last updated 2026-09-06.
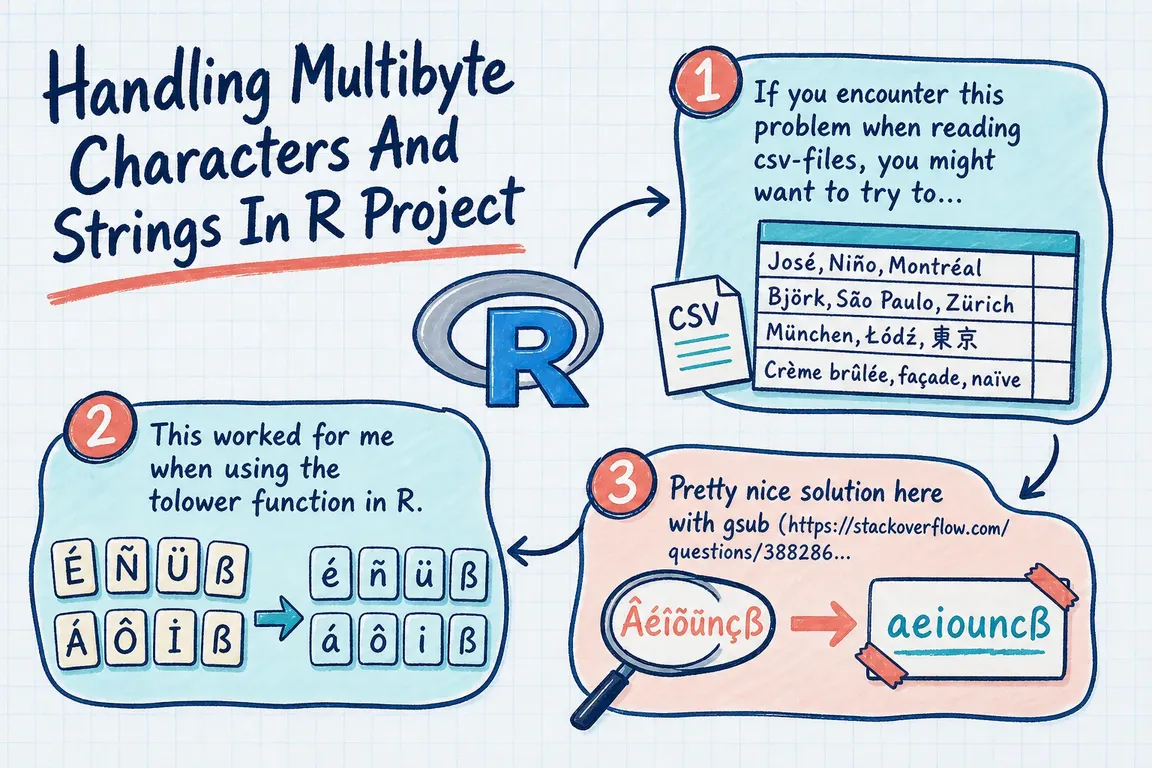
A CSV import can look fine until tolower() fails with an “invalid multibyte string” error. For a team preparing customer records, product feeds or agency reports, that can interrupt a routine delivery. A hurried fix can also remove meaningful characters from the data.
The practical approach is to identify the source encoding, read the file correctly and check representative records before continuing. Danish letters such as æ, ø and å belong in customer names and addresses. They should survive the import.
The earlier version of this article suggested switching from UTF-8 to Latin-1 and removing non-ASCII characters. Both techniques have specific uses, but neither is a general repair for broken text.
What causes multibyte string errors in R?
An encoding defines how bytes represent text. In UTF-8, a character may occupy several bytes. Problems arise when R interprets those bytes using an incompatible encoding, or when the input contains damaged or mixed text.
Start with the export settings of the system that produced the CSV. Ask for its declared encoding and keep an untouched copy of the file. Changing an import setting until the error disappears is insufficient evidence that the text is correct.
| Symptom | What to investigate | Practical next step |
|---|---|---|
| Names look wrong immediately after import | The file may have been decoded incorrectly | Confirm the export encoding and reimport the original file |
tolower() fails on some records |
Invalid bytes or inconsistent encoding | Isolate affected values and inspect their source |
| Only certain supplier files fail | Different export settings across suppliers | Define an import configuration for each source |
| A destination requires ASCII | An explicit restriction on permitted characters | Create a separate export field and review the information lost |
Read the CSV with its actual encoding
In base R, fileEncoding specifies the file’s encoding and enables conversion during import. The similarly named encoding argument marks strings; it does not re-encode the input. That distinction is documented in R’s data import reference.
# Use the encoding confirmed by the exporting system.
source_encoding <- "UTF-8"  # Change to "latin1" only if confirmed.

df <- read.csv(
  "customers.csv",
  fileEncoding = source_encoding,
  colClasses = "character"
)
Reading columns as text during diagnosis helps preserve identifiers with leading zeros. Convert numeric and date columns deliberately afterwards. For semicolon-separated files with decimal commas, use read.csv2().
Base R’s file conversion targets the current locale, which can limit the characters it represents. If your project uses readr, its import functions produce UTF-8 strings and let you specify the source encoding explicitly:
df <- readr::read_csv(
  "customers.csv",
  locale = readr::locale(encoding = source_encoding),
  col_types = readr::cols(.default = readr::col_character())
)
If the encoding is undocumented, readr::guess_encoding("customers.csv") can suggest candidates. Treat these as clues: the readr locale documentation shows that a plausible guess can still produce incorrect letters. Compare imported names and punctuation with known originals. If the exporter specifies Windows-1252, use that explicitly rather than assuming it is identical to Latin-1.
Convert existing strings without hiding failures
Encoding(text) reports declared encodings, not a reliable detection of the original file format. A result of "unknown" does not automatically mean damaged text; ASCII strings are normally unmarked. Assigning Encoding(text) <- "UTF-8" changes the declaration without converting the bytes. See R’s encoding reference.
If a character vector still contains bytes in a known source encoding, use iconv(). This small example deliberately constructs a Latin-1 name:
text <- c("S\xf8ren", NA_character_)
converted <- iconv(text, from = "latin1", to = "UTF-8", sub = NA)

failed <- which(!is.na(text) & is.na(converted))
if (length(failed) > 0L) {
  stop("Encoding conversion failed; review the original values.")
}
This distinguishes conversion failures from values that were already missing. Avoid sub = "" during diagnosis because it discards unconvertible bytes. Conversion behaviour varies across platforms, and a successful conversion does not prove the source encoding was correct. Those limitations are covered in R’s iconv documentation.
Do not apply a Latin-1 conversion to data already correctly imported as UTF-8. When the earlier import is suspect, return to the original file.
Apply lowercase conversion after fixing the input
Once the text is correctly decoded, create a separate field such as df$customer_name_lower <- tolower(df$customer_name). Preserve the original name for display and review.
Case conversion depends on the platform and locale, as R’s case conversion documentation explains. Check examples from the languages you actually process on the machine running the scheduled job. A lowercase name alone should not become a customer identifier.
When the original gsub command is appropriate
The original command remains useful when a destination explicitly accepts only printable ASCII:
ascii_text <- gsub('[^\x20-\x7E]', '', text)Run it on correctly decoded text and keep the result separate. It removes everything outside ASCII space through tilde, including accented letters, emoji, tabs and line breaks. “Søren” becomes “Sren”. It deletes characters rather than transliterating them, so it is unsuitable as routine cleanup for names or addresses.
Make the fix part of the workflow
Before accepting an import, reconcile record counts, inspect warnings, compare missing values and check a small sample containing international characters. Keep those examples as repeatable checks for the next export. Document the source encoding, delimiter and person responsible for resolving failures.
If recurring CSV problems are delaying reporting or client delivery, talk to Greg about the import workflow. Bring the failing command, export settings and an anonymised sample that preserves the problematic bytes. That gives the investigation a concrete starting point.
Related on GrN.dk
- PHP CSV Parsers: Practical Choices for Real-World Imports
- MySQL Zero-Date Import Errors: A Safer Fix for Legacy Data
- Mysqldump Encoding: How to Prevent Broken Characters in Database Exports
Need help with this kind of work?
Talk to Greg about your data import workflow Get in touch with Greg.