By Greg Nowak. Updated 2 September 2026.
Robots.txt used to be a housekeeping file: let search engines reach useful pages, keep them out of staging areas and prevent wasted crawling. That is still important, but it is no longer the whole decision.
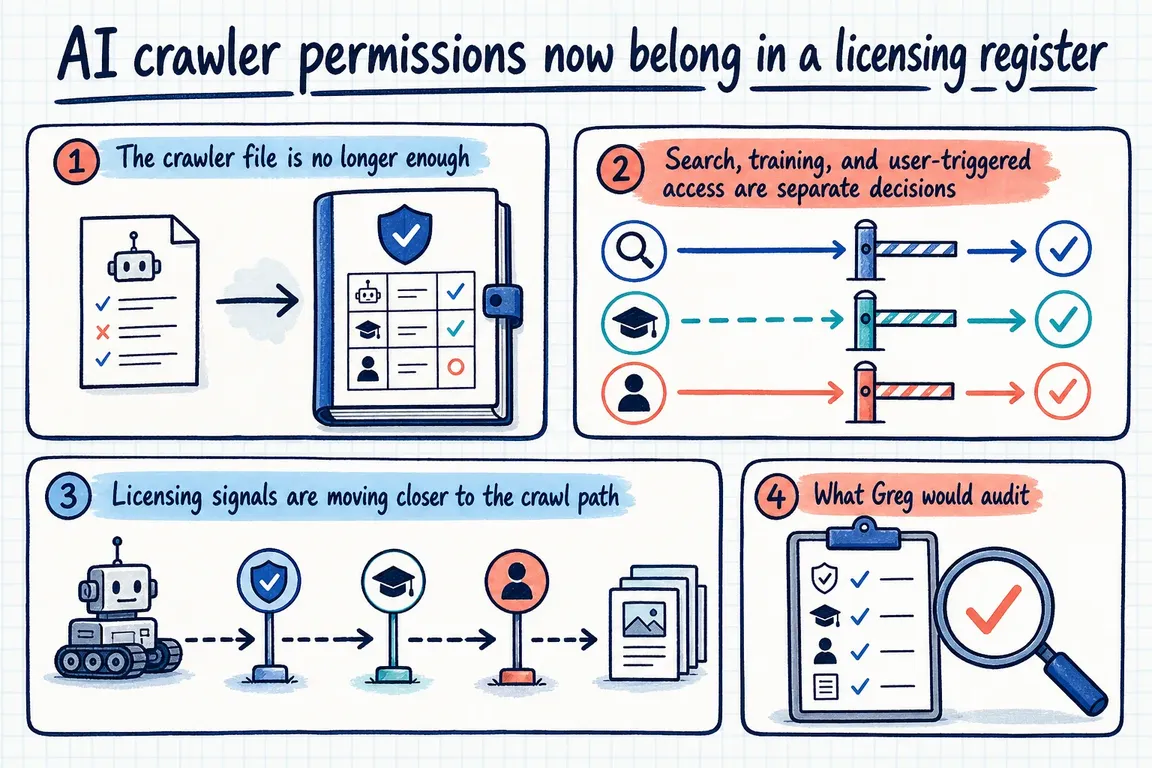
A public page may now be used for conventional search results, an AI-generated answer, model training or a request initiated by an individual user. Those uses have different commercial consequences. Treating every crawler as either “allowed” or “blocked” leaves too much room for accidental decisions.
The practical answer is a crawler licensing register: one maintained record connecting each intended use with the relevant content, crawler token, published terms, technical control, evidence and owner.
Robots.txt is a control file, not the policy
Robots.txt manages which URLs compliant crawlers may request. It does not establish a complete content strategy, reliably prevent access or keep confidential information private. Sensitive material still belongs behind authentication or another real access control.
Cloudflare makes the distinction explicit. Its managed robots.txt feature can publish content signals for search indexing, real-time AI input and AI training. Cloudflare also describes robots.txt compliance as voluntary and recommends AI Crawl Control when a site needs technical enforcement.
This creates three separate layers that should not be confused:
- Policy: what the business wants to permit, refuse or license.
- Publication: robots.txt, content signals or machine-readable licensing terms.
- Enforcement: authentication, CDN or WAF rules, bot controls and monitoring.
Decide by use, not by the word “AI”
| Intended use | Business decision | Control or evidence to record |
|---|---|---|
| Search discovery | Should these pages appear in links and conventional search results? | Search crawler rules, indexability checks and referral visibility. |
| AI answers and grounding | Is answer visibility valuable, and for which public content? | Product-specific crawler tokens, content signals and test queries. |
| Model training | Is training permitted, prohibited or available under licence? | Training-crawler rules, licensing terms and access logs. |
| User-triggered retrieval | May an assistant fetch a page when a person explicitly requests it? | User-agent and IP verification, rate limits and protected-path tests. |
| Commercial reuse | Are attribution, payment or a negotiated agreement required? | RSL or other published terms, contract owner and licence history. |
The crawler names matter because apparently similar products expose different controls. Googlebot affects Google Search. Google-Extended is a separate robots.txt control token for specified Gemini training and grounding uses; Google says it does not affect Search inclusion or ranking. It is not a separate HTTP user agent, so searching access logs for “Google-Extended” will not prove that the preference was followed.
OpenAI likewise separates OAI-SearchBot, used for ChatGPT search visibility, from GPTBot, which covers content that may be used for training. ChatGPT-User represents certain user-initiated visits and is not an automatic web crawler; OpenAI warns that robots.txt may not apply to those requests.
A sensible starting configuration
A business that wants ordinary search and ChatGPT search visibility while declining the documented training uses might begin with rules like these:
User-agent: Googlebot
Allow: /

User-agent: Google-Extended
Disallow: /

User-agent: OAI-SearchBot
Allow: /

User-agent: GPTBot
Disallow: /
This is an example, not a universal recommendation. It also does not cover every crawler, prevent impersonation or override user-triggered access. Before publishing it, test the file for accidental conflicts with existing wildcard groups and path-specific rules. OpenAI says its search systems may take roughly 24 hours to adjust after a robots.txt change.
If the business has licensing terms, RSL 1.0 provides a machine-readable XML format and several discovery mechanisms. A site-level starting point can be a licence reference in robots.txt:
License: https://example.com/ai-license.xmlPublishing a licence reference is not the same as completing a commercial or legal review. The register should identify the covered assets, permitted uses, payment or attribution conditions, responsible contract owner and enforcement method. Have appropriate counsel approve terms that are meant to carry legal weight.
What belongs in the register
A spreadsheet can work initially, provided it is treated as an operational record rather than a forgotten inventory. Give each row a content scope and intended use. Then record the crawler or control token, current decision, robots.txt group, licensing reference, enforcement rule, evidence source, accountable owner, approval date and next review date.
Segment by content value rather than assuming the whole domain deserves one rule. Marketing pages may benefit from broad discovery. Original research, paid archives, product data, customer portals and downloadable media may need different terms or stronger access controls. Record exceptions explicitly so an infrastructure change does not silently flatten them.
Run the register as a lightweight control
- Inventory: collect the live robots.txt response, CDN settings, WAF rules and relevant server or edge logs. Check what visitors actually receive, not only what the CMS contains.
- Agree the outcomes: ask content, marketing, operations, security and commercial owners what each content group is meant to achieve.
- Translate decisions: map outcomes to crawler-specific rules, content signals, licensing documents and genuine access controls.
- Validate: test permitted and prohibited paths, verify documented IP ranges where available, and watch for unexpected volume or unidentified agents.
- Review changes: revisit the register when a provider changes its crawler documentation, the site launches a valuable content type or a commercial agreement changes.
The useful management question is therefore not “Do we block AI?” It is “Which uses create value, which require terms, and how will we know our decision is being followed?”
If crawler settings currently sit between SEO, infrastructure and legal ownership, Greg can help turn them into a documented policy, tested configuration and manageable review process. Talk to Greg about a crawler permissions audit.
Related on GrN.dk
- AI crawler policy now has verbs: separate search, RAG, and training
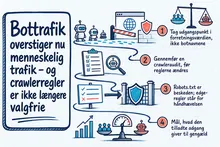
- Bot traffic now exceeds human traffic—and crawler rules are no longer optional
- ChatGPT Visibility Without Opening Every Door: robots.txt Is Only the Start
Need help with this kind of work?
Ask Greg to review your crawler policy Get in touch with Greg.